> ## Documentation Index
> Fetch the complete documentation index at: https://docs.dqlabs.ai/llms.txt
> Use this file to discover all available pages before exploring further.
# Anomaly Detection
> How Prizm's anomaly detection builds statistical baselines, scores drift and outliers, and assigns alert priority, illustrated with a volume metric example.
### How anomaly detection works (Volume as an example)
Prizm monitors volume by building a **statistical baseline** from historical runs and comparing each new value against it. There are no thresholds to manually configure — the system learns the normal range for each asset and flags deviations automatically.
**Step 1 — Baseline construction.** Over the first several runs, Prizm observes the row count and data size of the asset and establishes an expected range. The baseline is represented as a distribution — the grey bell curve on the left side of the Anomaly Distribution chart on the metric overview page.
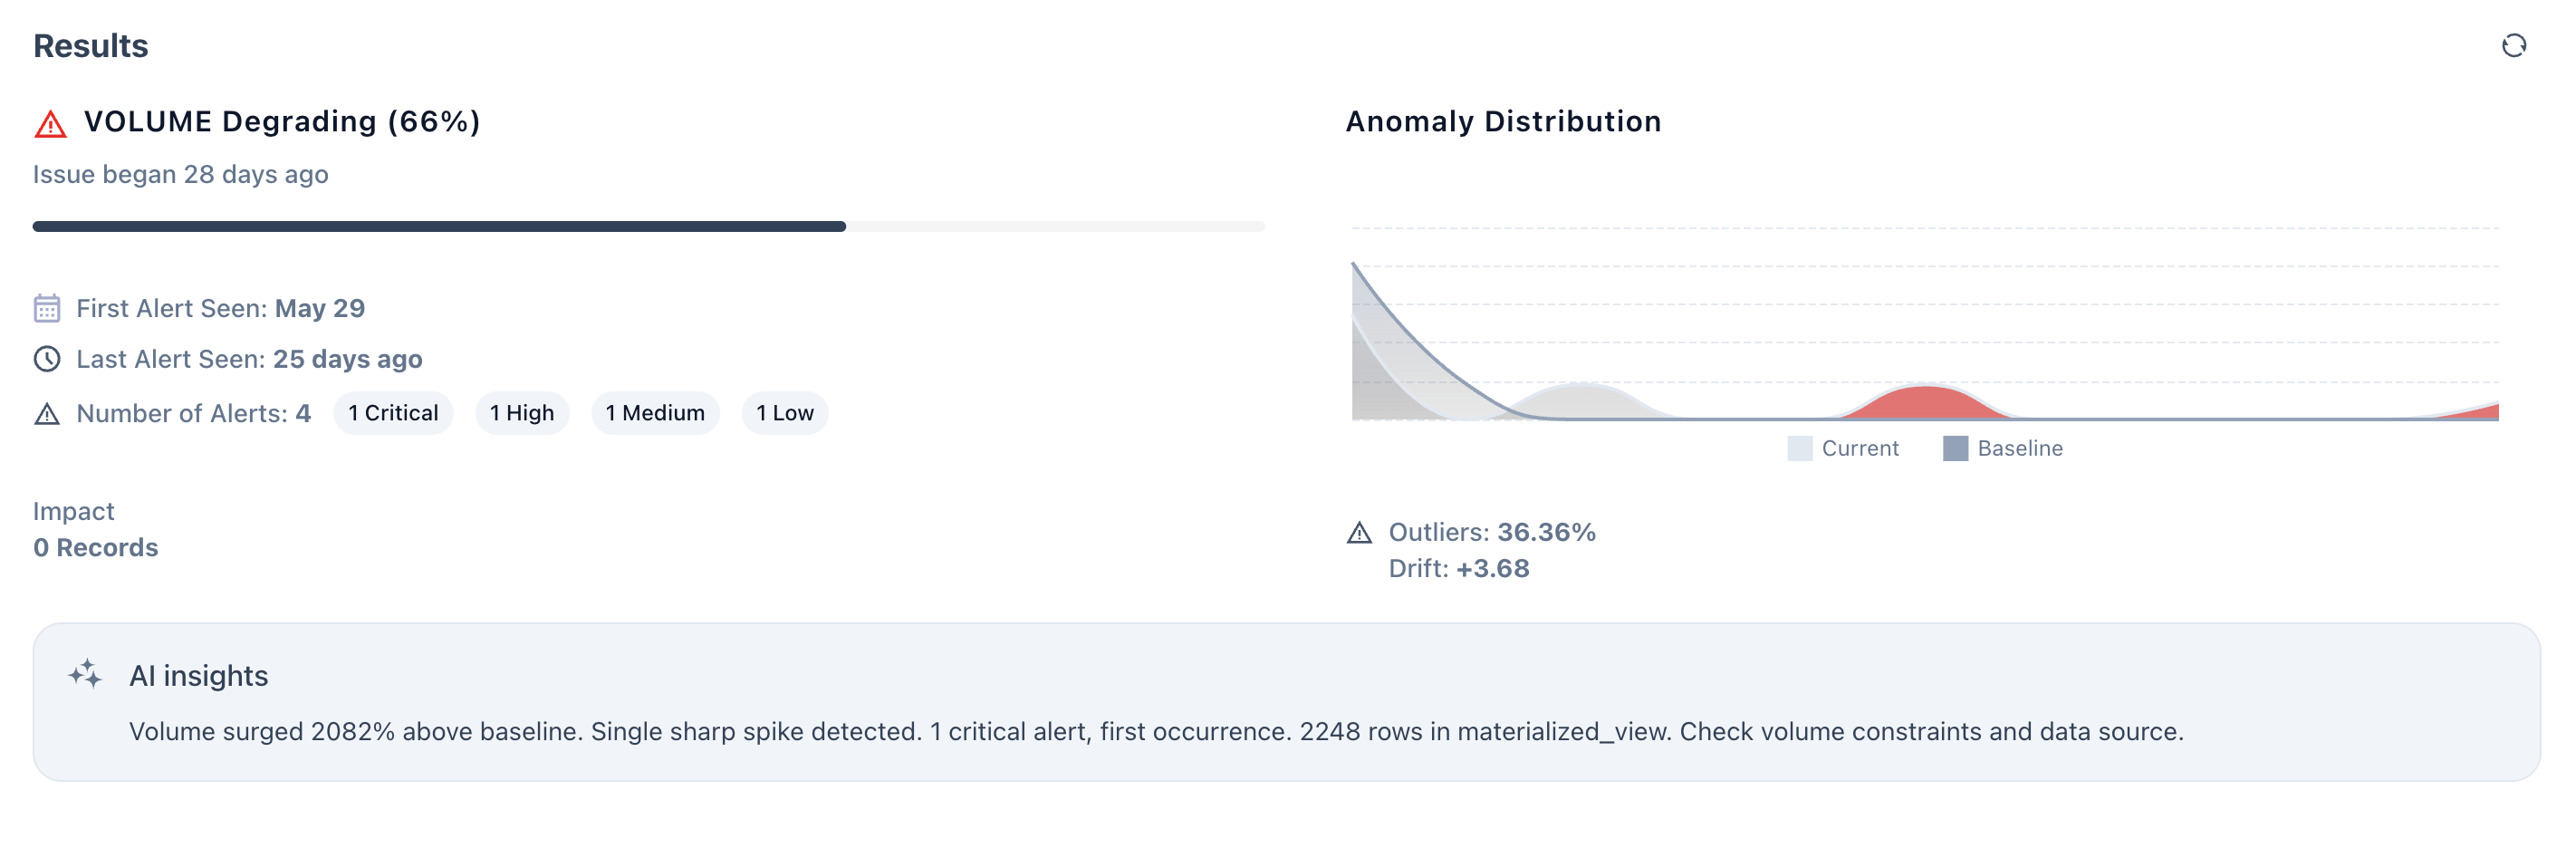
**Step 2 — Deviation scoring.** Each new run produces a value that is compared against the baseline distribution. Prizm computes a **drift score** — how far the new value sits from the centre of the expected range, expressed in standard deviations. A drift of +3.68 (as shown in the screenshot) means the current value is 3.68 standard deviations above the baseline mean.
**Step 3 — Outlier classification.** Values that fall outside the expected range are classified as outliers. The **Outliers %** figure (36.36% in the screenshot) represents the proportion of recent runs that produced an anomalous value. A high outlier percentage means the asset has been behaving abnormally for a sustained period, not just a one-off spike.
**Step 4 — Alert prioritisation.** Prizm assigns a priority to each anomaly based on the magnitude of the drift and the direction of the change. The four priority levels are:
 | Priority | When it fires | Example from screenshot |
| -------- | -------------------------------------------------- | --------------------------------------------------------------------- |
| Critical | Extreme deviation far outside the baseline | May 29 2:37 PM — actual 2,248 vs expected 103–103, change +2,083% |
| High | Large deviation significantly outside the baseline | Jun 1 10:01 AM — actual 49,256 vs expected 11,193–31,867, change +95% |
| Medium | Moderate deviation outside the expected range | Jun 1 9:36 AM — actual 25,256 vs expected 5,074–14,386, change +106% |
| Low | Minor deviation at the edge of the expected range | Jun 1 9:54 AM — actual 25,256 vs expected 7,477–24,972, change 0% |
### Reading the anomaly distribution chart
The **Anomaly Distribution** panel on the Overview tab shows two overlapping curves:
* **Baseline (grey)** — the expected distribution of volume values learned from historical runs. A tight, tall curve means the asset has historically been very consistent. A wide, flat curve means the asset naturally varies a lot.
* **Current (red/orange)** — the distribution of recent run values. When this curve shifts right of the baseline, volume is higher than expected. When it shifts left, volume is lower than expected. The further apart the two curves are, the higher the drift score. The example in the screenshot shows the current distribution shifted far to the right of the baseline — consistent with the +3.68 drift score and the 2,082% spike recorded on May 29.
### Reading the metric timeline
The **Timeline tab** combines a line chart and a run history table into a single view for diagnosing volume anomalies over time.
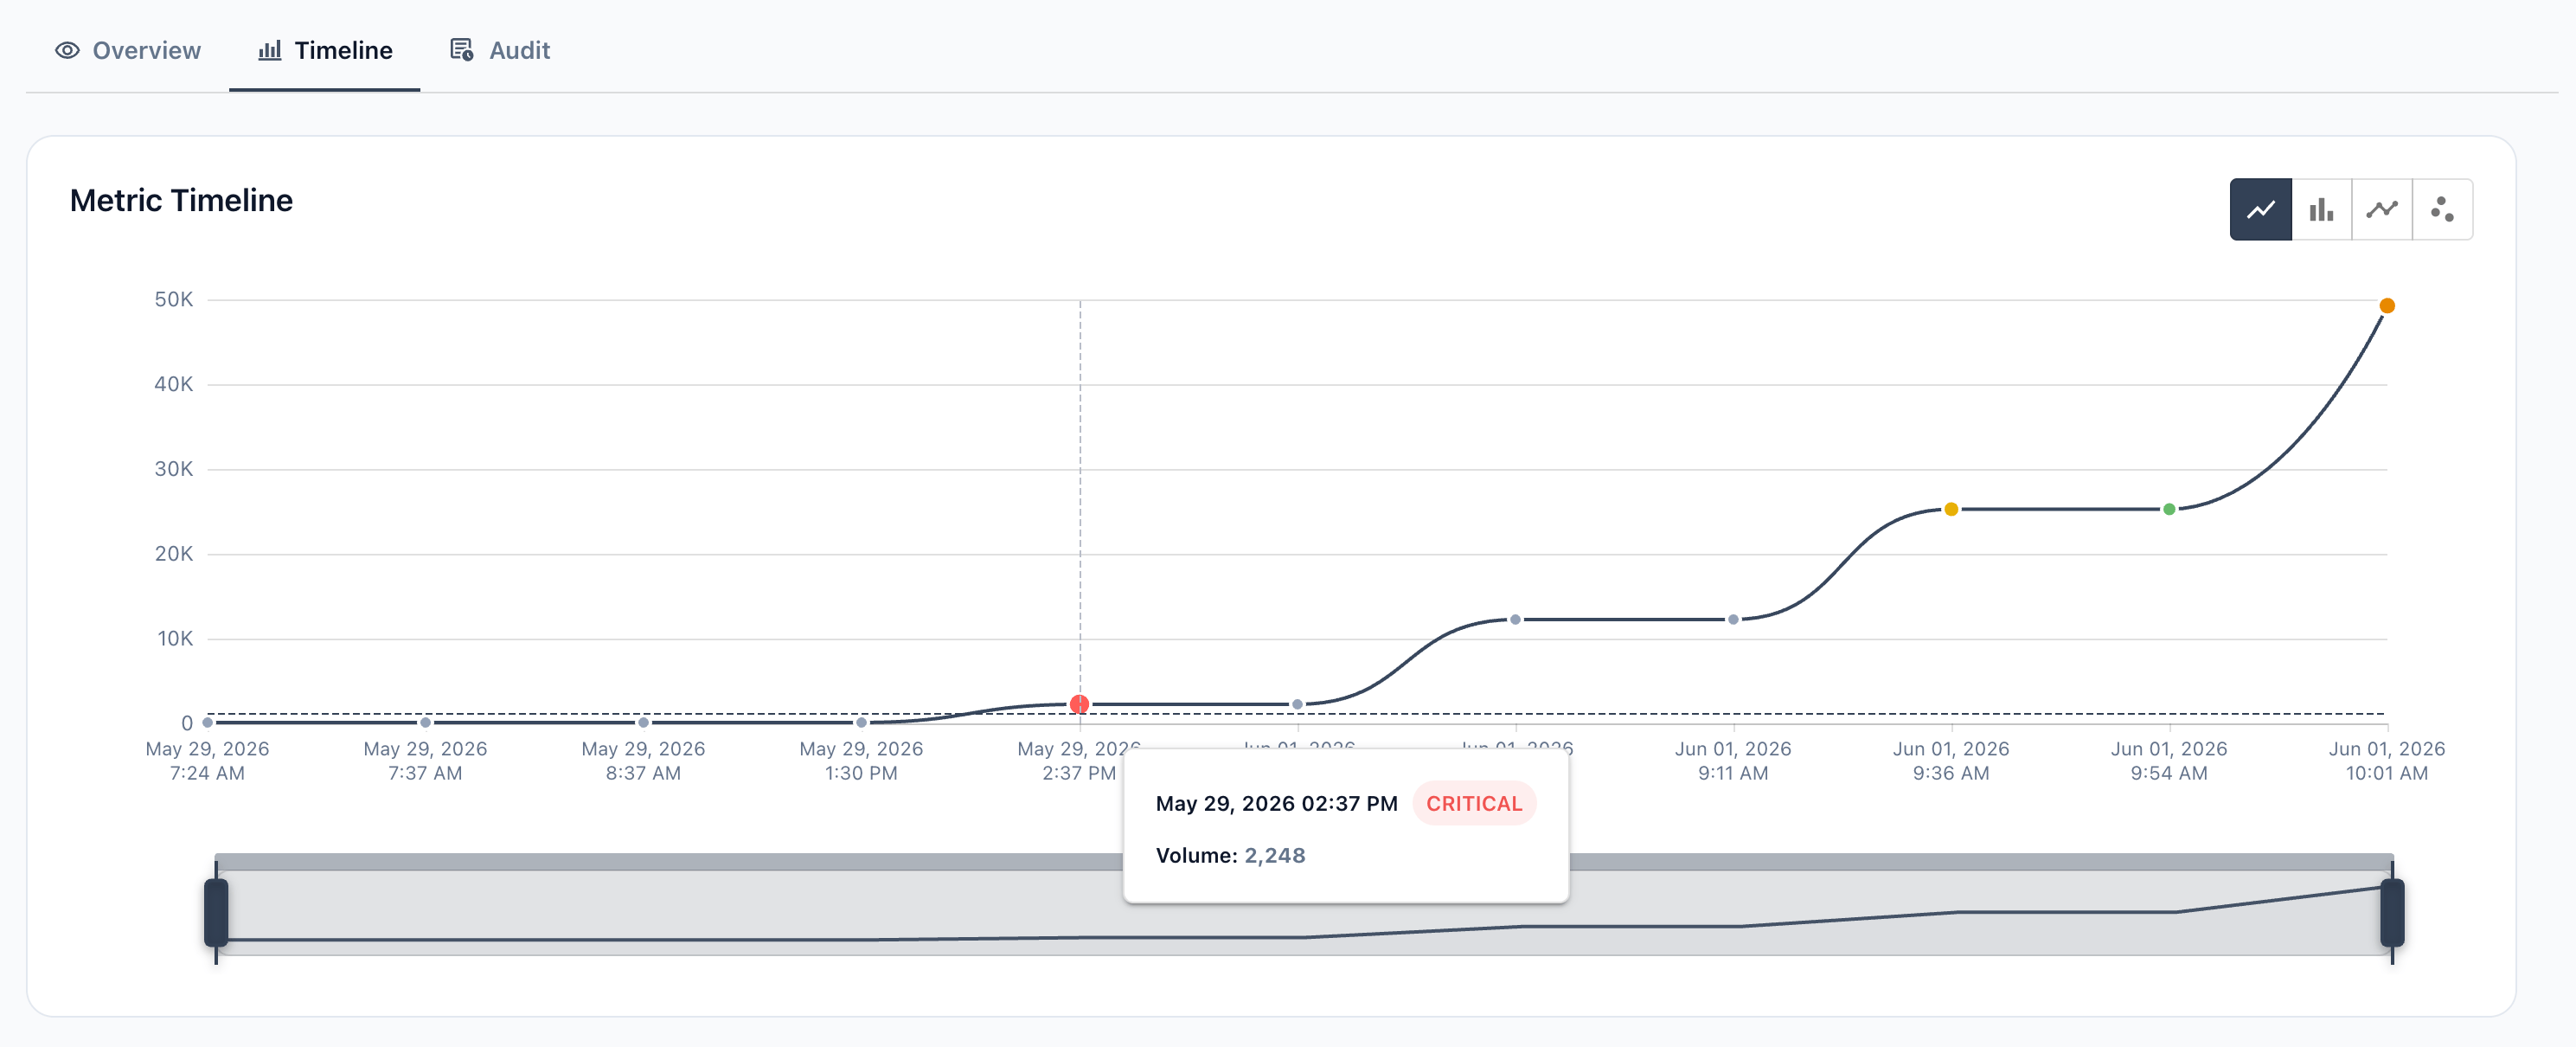
**Line chart (top)** — plots the actual row count for each run. The x-axis is time; the y-axis is row count. The red dot marks the first alert — in this case, May 29 at 2:37 PM when volume jumped from 103 to 2,248. The line then continues climbing through subsequent runs up to 49,256 by June 1 at 10:01 AM. The minimap below the chart lets you zoom in on any time window.
**Run history table (bottom)** — lists every run with the following columns:
| Column | What it shows |
| --------- | ----------------------------------------------------------- |
| Date Time | When the metric run executed |
| Expected | The baseline range Prizm predicted for this run (min – max) |
| Actual | The value Prizm observed |
| Alert | The alert message if a threshold was breached |
| Priority | Critical / High / Medium / Low / OK |
| Issue | Whether a linked issue was raised |
| Change % | The percentage change from the prior run |
| Marked As | Whether the alert was acknowledged or suppressed |
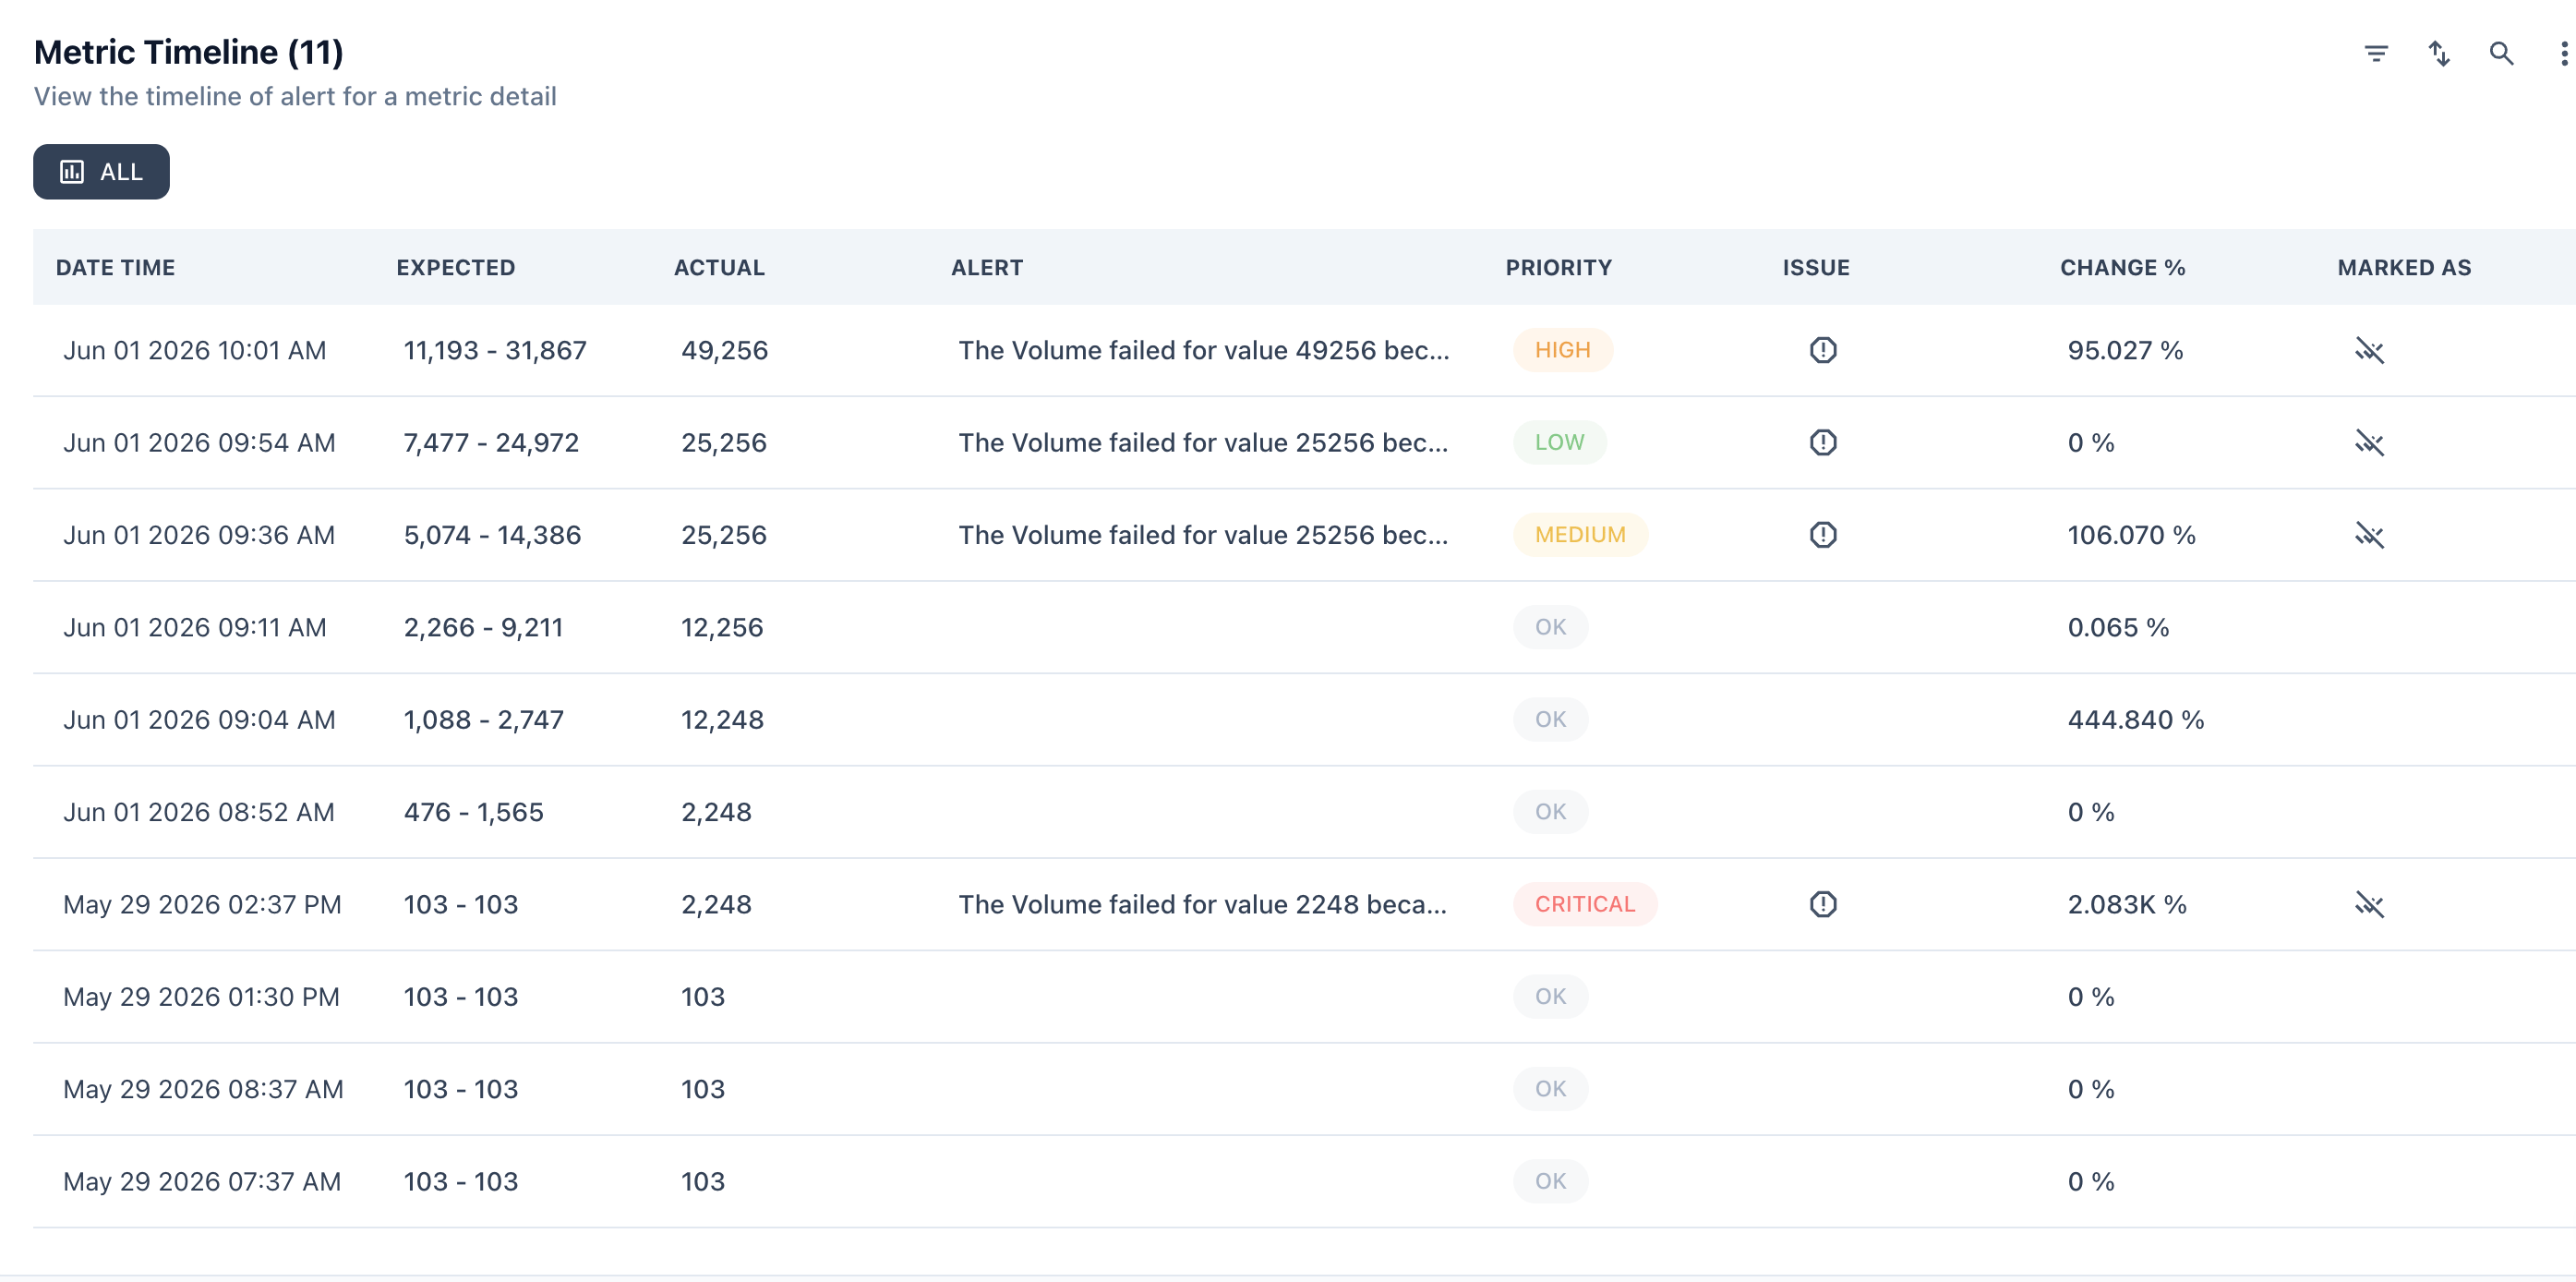 Rows marked **OK** fell within the expected range — no alert was raised. Rows with a **Critical**, **High**, **Medium**, or **Low** badge breached the baseline. The Change % column is the fastest way to spot the outlier run: in this example, the May 29 2:37 PM run shows +2,083K% — the moment the volume first spiked.
### The degrading state
When the Overview tab shows **VOLUME Degrading (66%)**, it means:
* The metric has been in an anomalous state for a sustained period (28 days in the example)
* The degradation percentage (66%) is the proportion of recent runs that produced an anomalous value — it combines outlier rate with drift magnitude to give a single health signal
* The first alert date (May 29) marks when the anomaly began, and the last alert date (25 days ago) marks the most recent breach This state persists until the volume returns to the expected baseline range and remains stable for enough consecutive clean runs for Prizm to re-establish a healthy baseline.
 Volume metrics are most effective when combined with Freshness. A row count within range but a stale `Last Updated` timestamp means data arrived on time historically but has not been refreshed recently — a subtler failure pattern that volume alone would miss.
### Business impact
| Scenario | Signal | Business impact |
| ------------------------------------ | ------------------------------------------- | ----------------------------------------------------------------------- |
| Row count drops to zero | Pipeline stopped delivering data | Dashboards show no data; analysts make decisions on empty reports |
| Row count drops 40% vs. prior run | Partial load or upstream filter change | Analysis is based on an incomplete dataset; aggregates are understated |
| Row count spikes 3× vs. prior run | Duplicate injection or re-run without dedup | Metrics are inflated; financial totals, counts, and KPIs are overstated |
| Data size grows with no row increase | Individual records have grown significantly | Storage costs increase; downstream ETL may time out or fail |
***