> ## Documentation Index
> Fetch the complete documentation index at: https://docs.dqlabs.ai/llms.txt
> Use this file to discover all available pages before exploring further.
# Setup
> Connect Prizm to dbt Cloud via API and webhook, or configure the dbt Core CLI plugin to push artifacts from your existing pipeline.
Prizm supports two integration modes for dbt. Choose based on your deployment:
| Mode | Best For |
| :------------ | :------------------------------------------------------------------------------------------------------------------------------------------------ |
| **dbt Cloud** | Teams using dbt Cloud for orchestration. Prizm connects via the dbt Cloud API and receives metadata via webhook or scheduled pull. |
| **dbt Core** | Teams running dbt Core in CI/CD, Airflow, or shell scripts. Prizm receives metadata via the `prizm-dbt` CLI plugin pushed after each dbt command. |
## Prerequisites
Before connecting, you need:
* A **dbt Cloud account** with access to the Admin API
* A **service token** with permission to read jobs, runs, and artifacts
* Your **account ID** and **access URL** (varies by region)
Service tokens are the recommended credential type. Personal access tokens can be used but are tied to an individual user account. Use service tokens for production integrations.
## Step 1 — Generate a Service Token
1. In dbt Cloud, navigate to **Account Settings → Service Tokens**
2. Click **New Token** and give it a descriptive name (e.g., `prizm-connector`)
3. Assign the following permission sets:
* **Metadata Only** (to read job definitions, run history, and artifacts)
4. Click **Save** and copy the token — it is shown only once
## Step 2 — Find Your Account ID and Access URL
| Setting | Where to Find It |
| :------------- | :------------------------------------------------------------------------------------------------------------------------- |
| **Account ID** | Shown in dbt Cloud URL: `https://cloud.getdbt.com/accounts//` |
| **Access URL** | US: `https://cloud.getdbt.com` · EU: `https://eu.dbt.com` · AU: `https://au.dbt.com` · Single-tenant: provided by dbt Labs |
## Step 3 — Add dbt Cloud in Prizm
Navigate to **Source → Add** and select **dbt** from the source type grid.
Fill in the **Source Details** form (Step 1 of 2):
| **Field** | **Required** | **Description** |
| :-------------- | :----------- | :---------------------------------------------------------------------- |
| Connection Name | ✅ | A unique label for this connection (e.g., `dbt-cloud-prod`) |
| Description | Optional | Free-text description of this source |
| Platform Type | ✅ | Select **Cloud** for dbt Cloud |
| Use Vault | Optional | Enable to retrieve credentials from your configured secrets vault |
| Account ID | ✅ | Your dbt Cloud account ID (visible in the dbt Cloud URL) |
| Access URL | ✅ | Your dbt Cloud access URL (e.g., `https://oe527.us1.dbt.com`) |
| API Key | ✅ | Service token from dbt Cloud — stored encrypted, never shown after save |
| Project | Optional | Filter to a specific dbt project within the account |
| Environment | Optional | Filter to a specific environment (prod / staging / dev) |
| Enabled Webhook | Optional | Set to **Yes** to receive near-real-time run events from dbt Cloud |
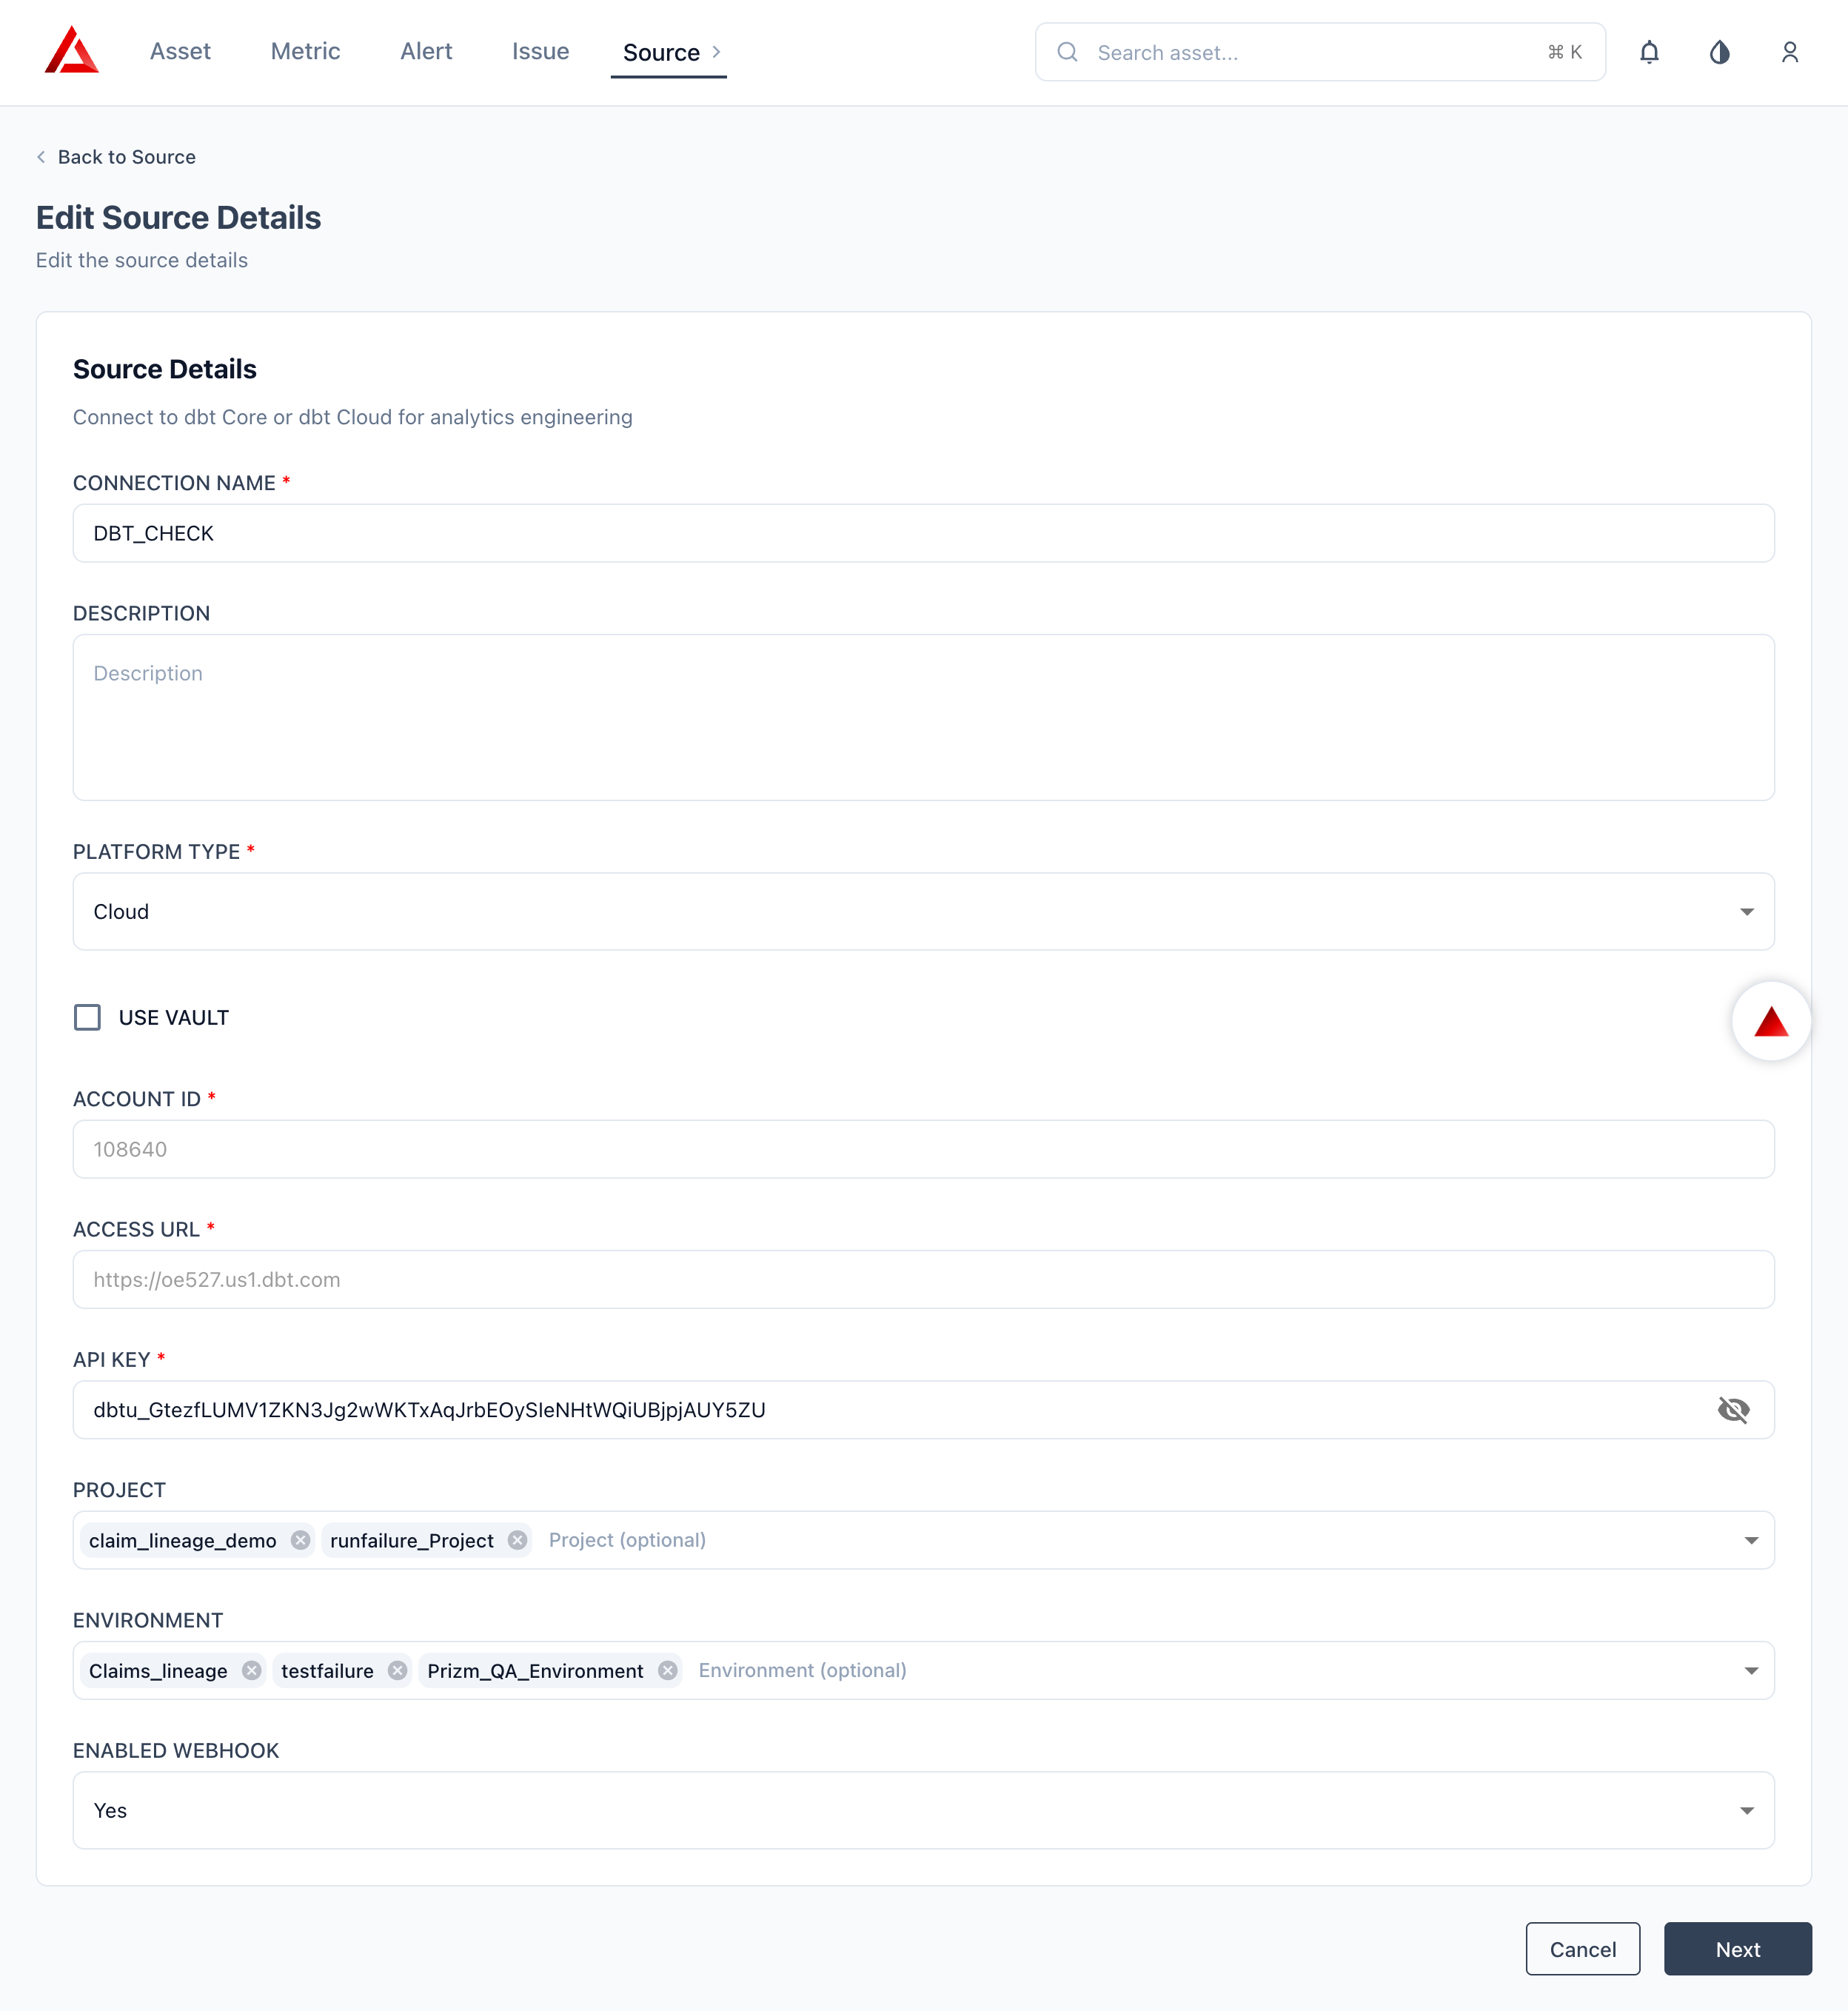 Set **Enabled Webhook** to **Yes** for near-real-time ingestion — Prizm processes artifacts within seconds of a dbt job completing. Leave it as **No** to use scheduled polling instead.
Click **Next** to proceed to the configuration step.
## Step 4 — Source Configuration
The second step configures semantic mapping and job automation for this dbt source.
**Semantic Configuration:**
| **Setting** | **Description** |
| :-------------------- | :-------------------------------------------------------------------------------- |
| Auto Mapping of Tags | Automatically maps dbt tags to Prizm semantic tags (Domain, Product, Application) |
| Auto Semantic Mapping | Enables AI-assisted classification of dbt assets into Prizm's semantic layer |
| Domain | Set a default domain for all assets from this source |
| Product | Set a default product classification |
| Application | Set a default application classification |
**Associated Assets Job:**
| **Setting** | **Description** |
| :------------------------------------------ | :--------------------------------------------------------------------------------------------------------------------------------------------------------- |
| Automatic Job Trigger for Associated Assets | When enabled, Prizm automatically runs observability jobs on warehouse assets (Snowflake, Databricks) that are associated with dbt models from this source |
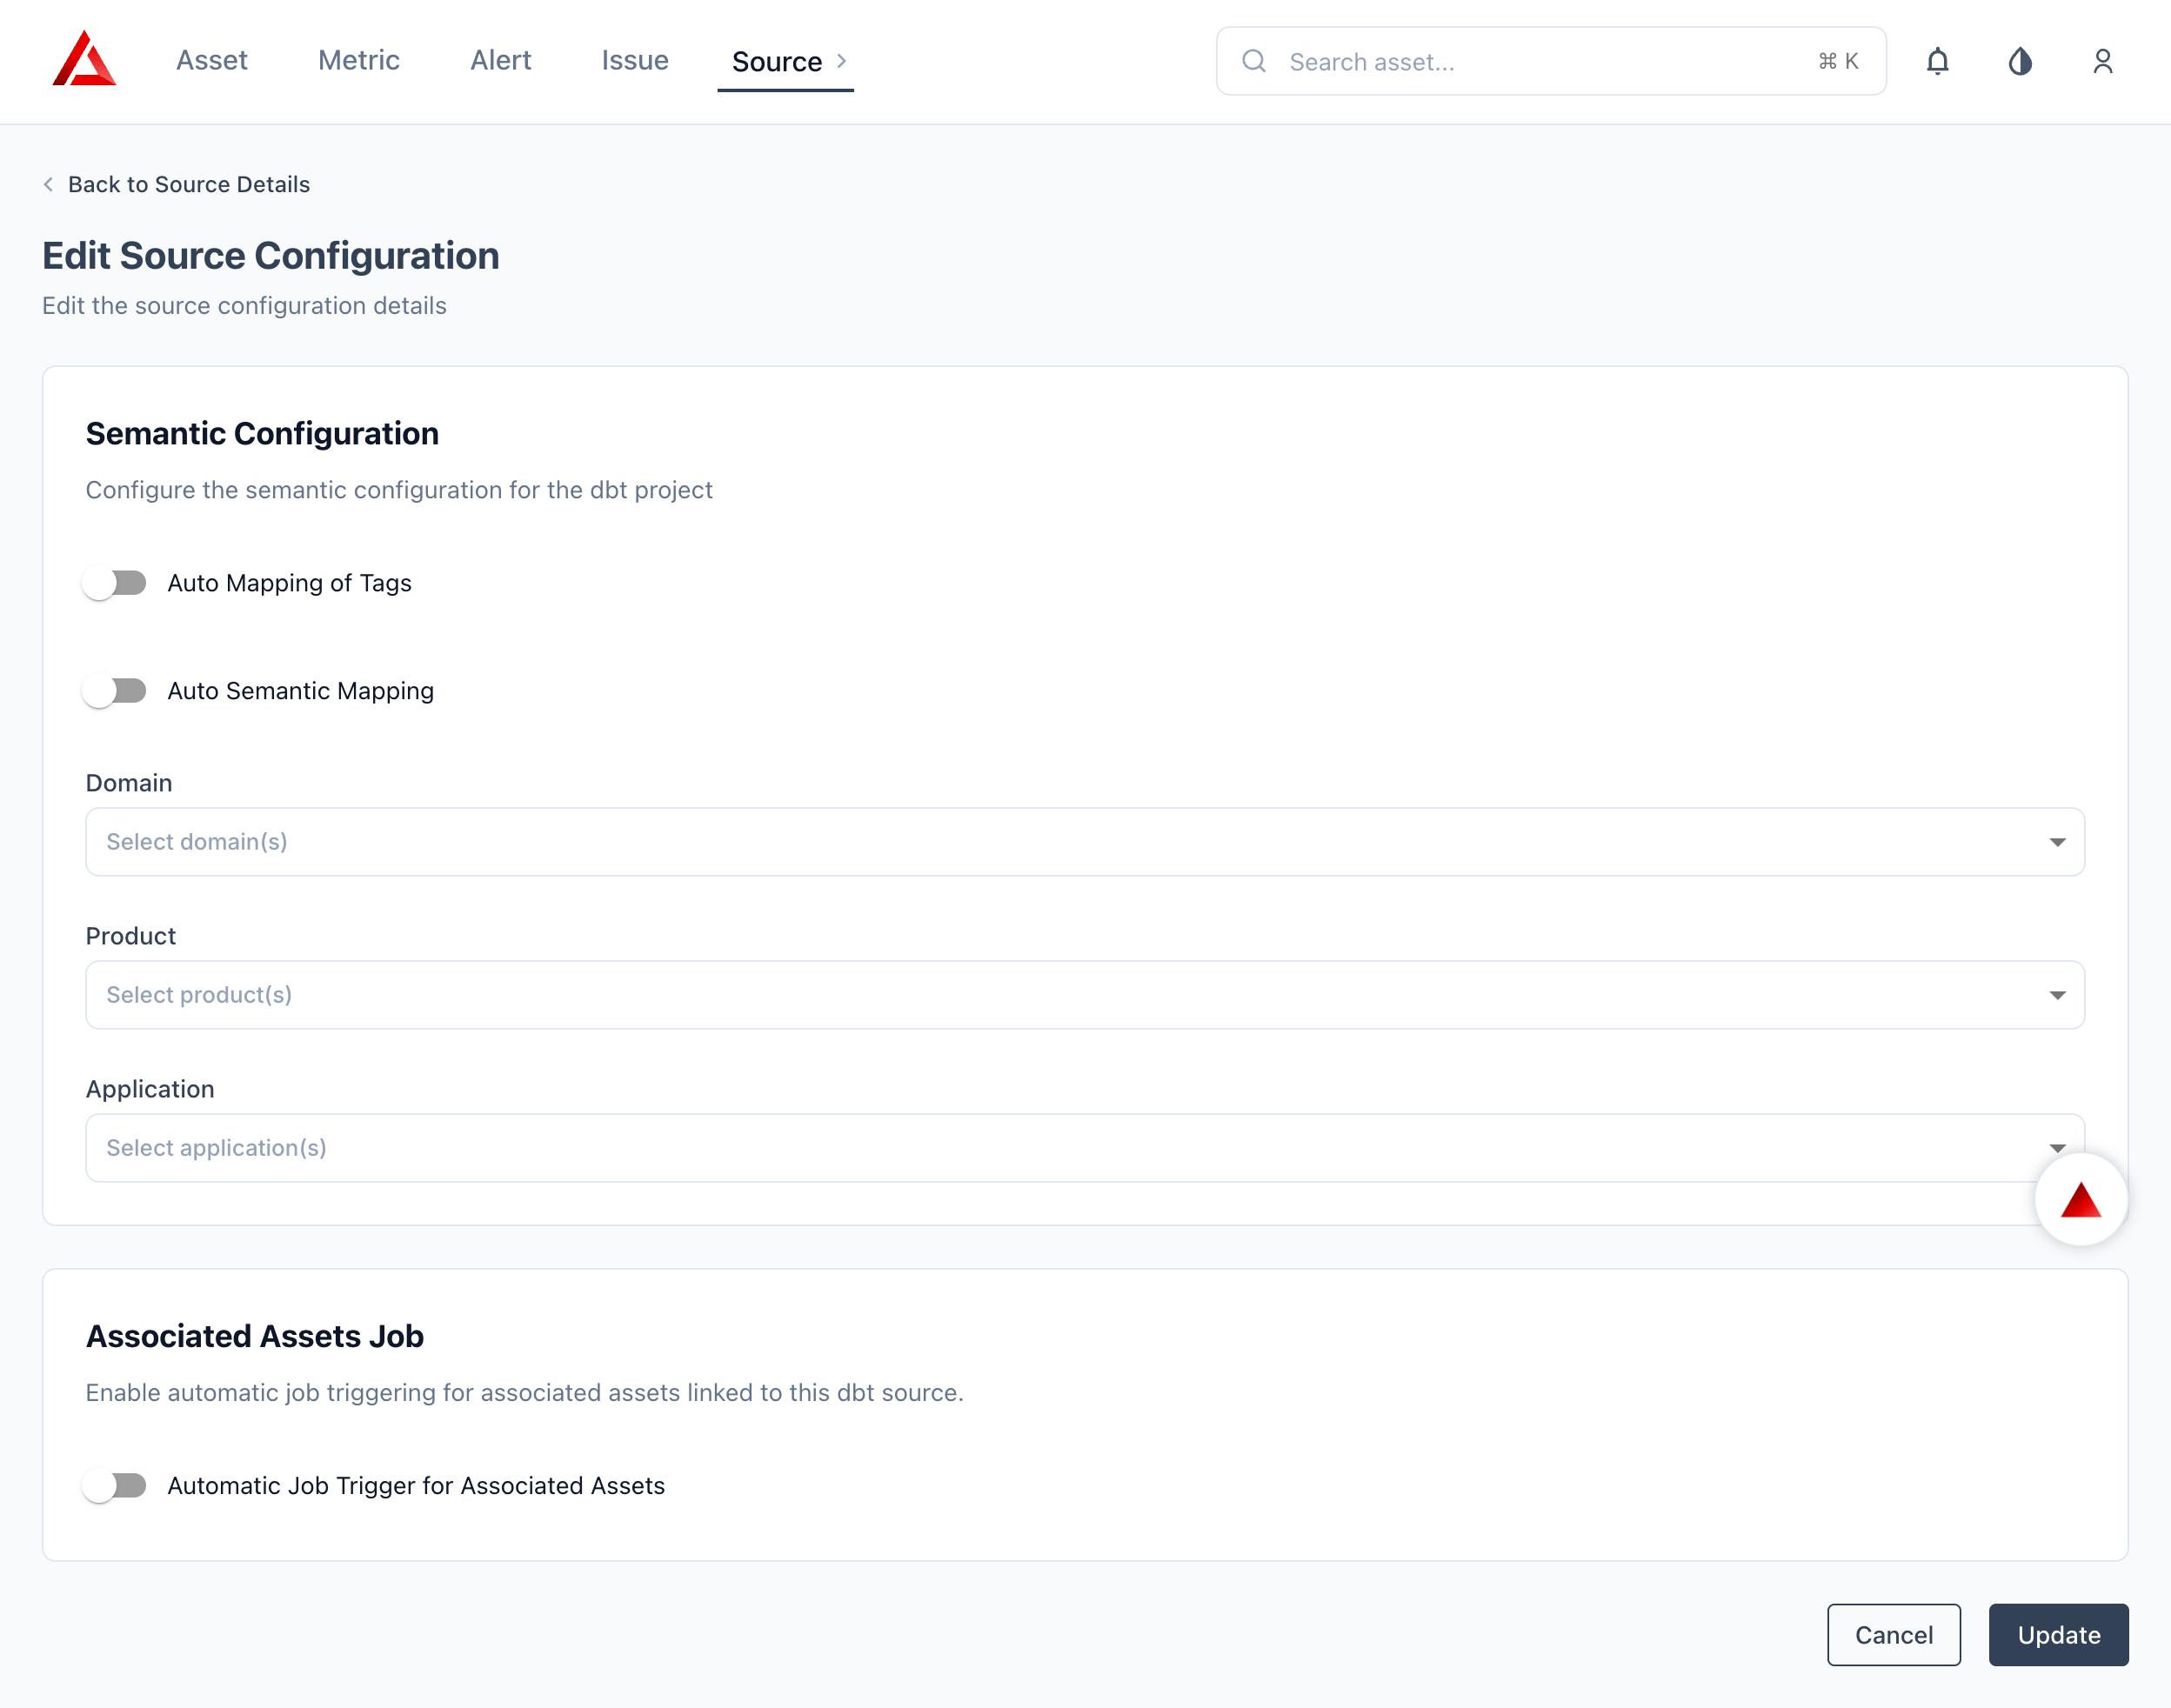 Click **Update** to save the configuration.
## Step 5 — Select Jobs to Monitor
After the connection is validated, Prizm presents a list of dbt Cloud jobs in the connected account. Select the jobs you want Prizm to monitor.
| **Column** | **Description** |
| :---------- | :--------------------------------------- |
| Job Name | dbt Cloud job name |
| Project | dbt project the job belongs to |
| Environment | prod / staging / dev |
| Schedule | Configured cron schedule or trigger type |
| Last Run | Timestamp of the most recent run |
You can restrict ingestion to specific projects or environments using the scope filter in the connector settings. By default, all jobs in the account are eligible for selection.
## Step 6 — Save and Verify
Click **Save**. Prizm immediately attempts to ingest the most recent completed run for each selected job. Navigate to **Settings → Sources → Logs** to monitor ingestion progress.
If the initial ingestion completes successfully, dbt models begin appearing in the Prizm catalog within a few minutes.
## Prerequisites
Before configuring the dbt Core integration, ensure:
* You have a dbt Core project running via CI/CD, Airflow, or shell scripts
* You can install Python packages in your pipeline environment
* A **Prizm API token** is available (from **Settings → API Tokens**)
## Install the prizm-dbt CLI Plugin
Install the `prizm-dbt` package in the same environment where dbt runs:
```bash theme={null}
pip install prizm-dbt
```
Set your authentication token as an environment variable:
```bash theme={null}
export PRIZM_API_TOKEN=
```
## Add dbt Core in Prizm
Navigate to **Source → Add** and select **dbt** from the source type grid.
 Fill in the **Source Details** form (Step 1 of 2):
| **Field** | **Required** | **Description** |
| :-------------- | :----------- | :-------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| Connection Name | ✅ | A unique label for this connection (e.g., `dbt-core-prod`) |
| Description | Optional | Free-text description |
| Platform Type | ✅ | Select **Core** for dbt Core |
| Ingestion Mode | ✅ | **CLI** — artifacts are pushed via the `prizm-dbt` CLI plugin after each dbt run. **Storage** — artifacts are pulled from a configured S3, GCS, or Azure Blob path on a schedule. |
Click **Next** to proceed. On the **Source Configuration** step, configure semantic mapping defaults and the Associated Assets Job trigger (same options as dbt Cloud — see Step 4 in the dbt Cloud tab above).
After saving, Prizm generates a project-specific token and endpoint URL used by the CLI plugin.
## CLI Commands
### `prizm-dbt push-artifacts` — Primary Command
Run this command after each `dbt run`, `dbt test`, `dbt build`, or `dbt docs generate`:
```bash theme={null}
prizm-dbt push-artifacts \
--project-dir \
--target-path
```
| **Flag** | **Description** |
| :-------------- | :----------------------------------------------------------------- |
| `--project-dir` | Root directory of your dbt project (where `dbt_project.yml` lives) |
| `--target-path` | Directory where dbt writes artifacts (default: `./target`) |
**What this command does:**
* Reads `manifest.json` (required), `run_results.json`, `semantic_manifest.json`, and `catalog.json` from the target path
* Attaches execution context: environment, target, adapter type, dbt version, invocation timestamp
* Pushes all available artifacts to Prizm via the push-based API
* Does **not** execute dbt — safe to run in any CI/CD context
`manifest.json` is required. If it is missing, the command exits with an error and lists the paths checked. All other artifacts are optional — if not present, they are marked "not produced" without error.
**Example — GitHub Actions:**
```yaml theme={null}
- name: Run dbt
run: dbt build --profiles-dir .
- name: Push artifacts to Prizm
env:
PRIZM_API_TOKEN: ${{ secrets.PRIZM_API_TOKEN }}
run: |
prizm-dbt push-artifacts \
--project-dir . \
--target-path ./target
```
**Example — Airflow:**
```python theme={null}
BashOperator(
task_id="push_dbt_artifacts",
bash_command=(
"prizm-dbt push-artifacts "
"--project-dir /opt/airflow/dbt "
"--target-path /opt/airflow/dbt/target"
),
env={"PRIZM_API_TOKEN": "{{ var.value.prizm_api_token }}"},
)
```
***
### `prizm-dbt validate` — Preflight Check
Run before your first push to verify the environment is correctly configured:
```bash theme={null}
prizm-dbt validate
```
Checks performed:
* Authentication token is present and valid
* Prizm endpoint is reachable
* Project directory and target path can be resolved
* Required file read permissions exist
***
### `prizm-dbt doctor` — Diagnostics
Run to diagnose configuration issues or provide context to Prizm Support:
```bash theme={null}
prizm-dbt doctor
```
Outputs:
* Resolved `project_dir` and `target_path`
* Detected artifacts and their sizes
* Environment context (env, target, adapter)
* Connectivity check to Prizm
* Result of the most recent artifact push (if available)
***
## Central Storage Ingestion (Optional)
For regulated environments or teams that persist dbt artifacts in centralized storage, Prizm supports scheduled ingestion from:
| Storage | Supported |
| :------------------- | :-------- |
| Amazon S3 | ✅ |
| Google Cloud Storage | ✅ |
| Azure Blob / ADLS | ✅ |
Configure a storage-based source from the connector settings. Prizm polls the configured bucket path on a schedule and ingests any new artifacts found.
Storage-based ingestion is designed for asynchronous or backfill use cases. For near-real-time observability, the CLI plugin push is recommended.
## Next Steps
Full breakdown of every artifact, object, and field Prizm ingests from dbt.
Common questions about credentials, artifacts, lineage, and troubleshooting.