
- Technical
- Operational
- Lineage
- Performance
- Usage Summary
- Governance
- Criticality Recommendation
- Compute Metric
- Profile Recommendation
- Structural Recommendation
- Profile
- Structural
- Asset Detail Recommendation
- Business Metric Recommendation
- Metric Detail Recommendation
- Term Recommendation
- Alert Cluster
- Score Trend
- Purge
| Type | CONTEXT |
| Execution | Runs immediately after source is configured — first job in the pipeline |
| Object | Fields Collected | Snowflake Source |
|---|---|---|
| Account | Account name, region, cloud provider | SHOW ACCOUNTS |
| Warehouse | Name, size, type, state, created_on | SHOW WAREHOUSES |
| Database | Name, created_on, owner, comment | SHOW DATABASES |
| Schema | Name, database, created_on, owner | INFORMATION_SCHEMA.SCHEMATA |
| Table | Name, type, last_altered, row_count, is_iceberg, is_hybrid | INFORMATION_SCHEMA.TABLES |
| View | Same as Table + view_definition | INFORMATION_SCHEMA.VIEWS |
| Column | Name, data_type, ordinal_position, is_nullable | INFORMATION_SCHEMA.COLUMNS |
Prizm catalogs
TABLE and VIEW object types. Dynamic Tables, Stored Procedures, External Tables, and Materialized Views are not currently included in the catalog collection.| Type | CONTEXT / TRUST |
| Execution | Starts after TECHNICAL completes |
| Signal | Source | Description |
|---|---|---|
| Volume | INFORMATION_SCHEMA.TABLES (row_count) | Row count trend; anomaly alerts on drops/spikes |
| Freshness | INFORMATION_SCHEMA.TABLES (last_altered) | Time since last DDL or DML update; SLA breach alerts |
| Schema Change | INFORMATION_SCHEMA.TABLES (last_ddl) | Column additions, renames, type changes, removals |
Pausing and resuming a source. Freshness is computed at collection time as the interval since the asset was last altered. Pausing collection freezes the displayed freshness value at whatever it was when the pause took effect — Prizm has no way to know the asset went untouched during the pause versus simply not being checked. When collection resumes, the first run measures the entire pause duration as staleness, which typically fires a critical freshness alert on every asset at once and writes that spike into the anomaly-detection baselines, distorting future thresholds.To avoid both the false alert storm and the baseline contamination when resuming a paused source: let the source’s underlying tables receive normal activity first, then let one full collection cycle complete and land before re-enabling downstream alerting, rather than re-enabling everything the moment the source itself reconnects.
| Type | CONTEXT |
| Execution | No scheduled run. Lineage does not appear on the schedule screen and does not fire automatically — it runs only when triggered manually from an individual asset’s run menu. |
ACCESS_HISTORY and QUERY_HISTORY to identify object dependencies and data flow.Lineage has no automatic schedule today. Trigger it manually per asset when you need current lineage data. Snowflake’s underlying
OBJECT_DEPENDENCIES view can lag up to 3 hours behind the actual DDL change, so a manual run immediately after a schema change may not yet reflect it — wait for the latency window to pass before re-running if the lineage graph looks stale.| Run | Method |
|---|---|
| First run — view lineage | Seeded from SNOWFLAKE.ACCOUNT_USAGE.OBJECT_DEPENDENCIES |
| First run — table lineage | Extracted per asset using SNOWFLAKE.CORE.GET_LINEAGE |
| Subsequent runs (DDL change detected) | Re-extracted only for assets with DDL changes; column-level lineage included (include_attribute_lineage = true) |
TABLE, VIEW, EXTERNAL_TABLE, MATERIALIZED_VIEW. Default batch size 100, concurrency 8.| Direction | What Prizm Shows |
|---|---|
| Upstream | Tables and views this asset reads from |
| Downstream | Tables, views, and pipelines that depend on this asset |
Lineage — both table-level and column-level — requires Snowflake Enterprise edition or above, since it depends on
SNOWFLAKE.CORE.GET_LINEAGE. Standard edition does not have a query-log-parsing fallback: on a Standard-edition account, the Lineage graph stays empty.| Type | CONTEXT |
| Execution | Runs in parallel after OPERATIONAL completes |
IMPORTED PRIVILEGES on the SNOWFLAKE database.| Category | Metrics | Source |
|---|---|---|
| Query Performance | Execution time, queue time, compilation time, bytes scanned, bytes written, rows produced, status | ACCOUNT_USAGE.QUERY_HISTORY |
| Warehouse Compute | Credits used per warehouse per hour | ACCOUNT_USAGE.WAREHOUSE_METERING_HISTORY |
| Storage | Average bytes stored (tables, fail-safe, stage) | ACCOUNT_USAGE.DATABASE_STORAGE_USAGE_HISTORY |
| Data Transfer | Bytes transferred to external destinations | ACCOUNT_USAGE.DATA_TRANSFER_HISTORY |
| Access History | User, query, objects read/written, timestamp | ACCOUNT_USAGE.ACCESS_HISTORY |
ACCOUNT_USAGE views have a data latency of up to 45 minutes. Prizm retains time-series observability data, quality score history, and query usage history for a default window of 90 days.| Type | CONTEXT |
| Execution | Runs in parallel after OPERATIONAL completes |
| What It Produces | Description |
|---|---|
| Usage frequency | Number of queries per asset over the past 7 days |
| Unique user count | Number of distinct users who accessed each asset |
| Access patterns | Read vs write activity, peak usage windows |
| Criticality inputs | Usage-based signals consumed by the CRITICALITY RECOMMENDATION job |
| Type | CONTEXT |
| Execution | Runs in parallel after OPERATIONAL completes |
IMPORTED PRIVILEGES on the SNOWFLAKE shared database for tag ingestion.| Object | Fields Collected | Snowflake Source |
|---|---|---|
| Tags*(Enterprise)* | Tag name, value, associated objects | ACCOUNT_USAGE.TAGS, TAG_REFERENCES |
| Business metadata | Owner, description, classification fields | INFORMATION_SCHEMA object properties |
| Type | CONTEXT |
| Execution | Runs in parallel after OPERATIONAL completes |
| Input Signal | Source Job |
|---|---|
| Usage frequency and user count | USAGE SUMMARY |
| Downstream dependency count | LINEAGE |
| Business metadata completeness | GOVERNANCE |
| Asset type and schema position | TECHNICAL / OPERATIONAL |
| Type | TRUST |
| Execution | Runs in parallel after OPERATIONAL completes |
INFORMATION_SCHEMA.TABLES.LAST_ALTERED) — but for assets like views and external tables, metadata alone is not sufficient. COMPUTE METRIC fills this gap by executing lightweight SQL queries to obtain accurate signals.| Asset Type | What Is Computed | How |
|---|---|---|
| View | Row count, freshness | Direct SELECT COUNT(*) and query history lookup |
| External Table | Row count, last modified | Query against external stage metadata |
| Materialized View | Row count, refresh timestamp | Query against materialized view metadata |
| Type | TRUST |
| Execution | Runs in parallel after OPERATIONAL; PROFILE job depends on its output |
| Type | TRUST |
| Execution | Runs in parallel after OPERATIONAL; STRUCTURAL job depends on its output |
| Type | TRUST |
| Execution | Triggered after PROFILE RECOMMENDATION completes and schedules are created |
| Metric | Description |
|---|---|
| Row Count | Total rows at profile time |
| Duplicate Row Count | Rows that are exact duplicates of another row |
| Completeness Score | % of columns with non-null values across all rows |
| Metric | Applicable Types | Description |
|---|---|---|
| Null Rate | All | % of null values |
| Distinct Count | All | Number of unique non-null values (cardinality) |
| Uniqueness Rate | All | % of values appearing exactly once |
| Min / Max | Numeric, Date/Timestamp | Observed range of values |
| Mean | Numeric | Arithmetic mean |
| Standard Deviation | Numeric | Statistical spread |
| Median | Numeric | 50th percentile value |
| Top N Values | String, Boolean | Most frequent values and their counts |
| Pattern Conformance | String | % matching an expected regex format |
| Data Type Conformance | String | % of values parseable as the declared type |
Advanced numeric statistics are computed for types containing
int, number, decimal, float, or double. Snowflake types such as REAL, BIGINT, and SMALLINT still receive min, max, distinct count, and null counts.| Trigger | Conditions |
|---|---|
| Scheduled run | Active schedule, next_run_at is due, source is valid and active |
| Manual run | User triggers Profile from the asset UI (TABLE, VIEW, MATERIALIZED_VIEW) |
| Platform mode | PROFILE job type must be enabled in platform mode |
| Criticality gating | Only attributes eligible for the asset’s criticality level are profiled |
| Skip (incremental) | Skipped if row count is unchanged since last run, or profile is newer than last_altered_on |
| Type | TRUST |
| Execution | Triggered after STRUCTURAL RECOMMENDATION completes and metrics are created |
| Metric Category | What Is Computed |
|---|---|
| Distribution | Null count, empty, space, distinct, repeating, character composition, leading/trailing/inner space |
| Frequency | Enum (value histogram), min/max value, value range, min/max length, length distribution |
| Pattern | Short pattern, long pattern, user-defined regular expressions |
| Statistics | Mean, median, mode, standard deviation, sum, Q1, Q3, range, skewness, kurtosis, variance, margin of error |
| Type | CONTEXT |
| Execution | Independent job; no upstream dependency |
| What It Generates | Description |
|---|---|
| Description | AI-generated plain-language description of what the asset contains and its purpose |
| Who should use | Recommended audience — data analysts, engineers, business users, etc. |
| Semantic context | Suggested domain, product, application, and tag classifications |
| Execution scope | Recommended profiling mode — Incremental (only changed rows), Sampling with Filter, or None |
| Type | TRUST |
| Execution | Independent job; no upstream dependency |
| Type | TRUST |
| Execution | Independent job; no upstream dependency |
| Type | CONTEXT |
| Execution | Independent job; no upstream dependency |
| Output | Description |
|---|---|
| Term mapping | Links a column to an existing glossary term (e.g. customer_id → “Customer Identifier”) |
| Term proposal | Suggests a new glossary term where no existing match is found |
| Confidence score | Indicates how confident the AI is in the mapping recommendation |
| Type | TRUST |
| Execution | Independent job; no upstream dependency |
| Type | TRUST |
| Execution | Independent job; no upstream dependency |
| Type | PLATFORM |
| Execution | Independent job; no upstream dependency |
None of the four recommendation jobs above (Asset Detail, Business Metric, Metric Detail, Term) can be generated in bulk — each produces suggestions for one asset at a time. The only bulk control available is Approve Recommendations on the asset page, which accepts already-generated suggestions for that asset’s pending recommendations; it does not create new ones. There is currently no control that generates recommendations across more than one asset at a time.
What You See in Prizm
Once Prizm completes its initial catalog and observability runs, every Snowflake table and view gets a unified asset detail page. The tabs below cover what each section shows.- Overview
- Attributes & Profile
- Metrics
- Usage
- Lineage
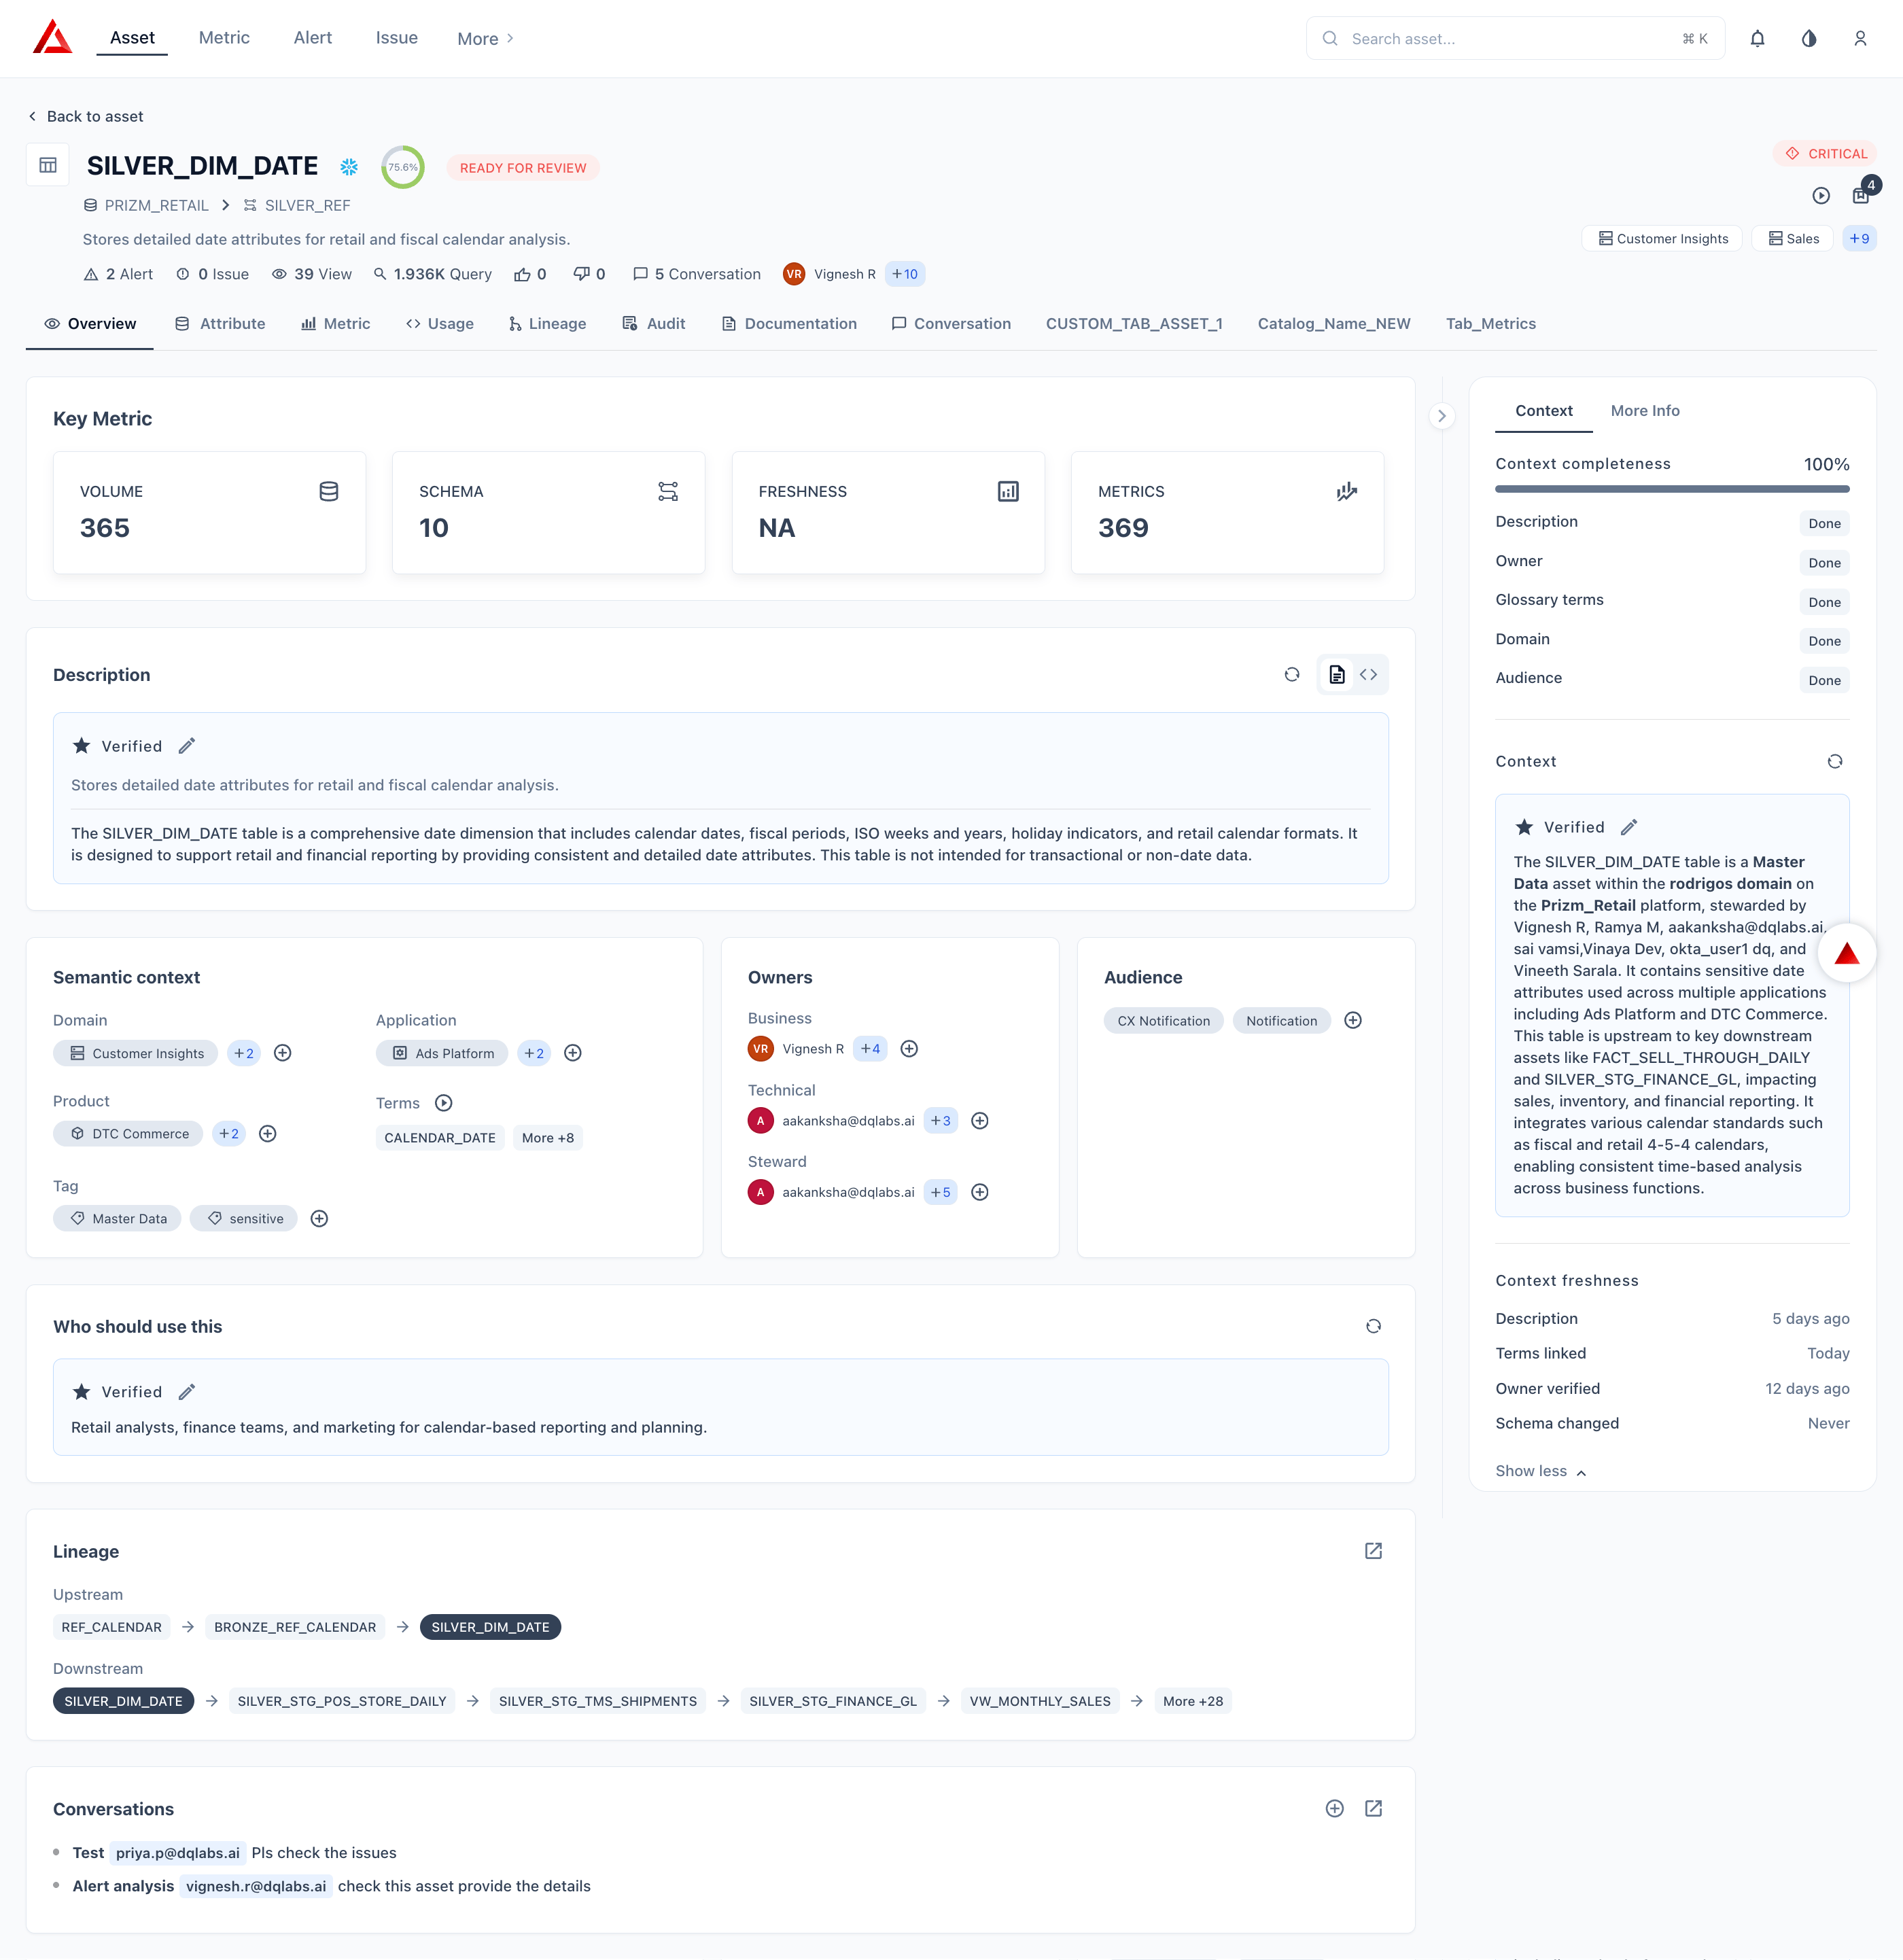
| Section | What Prizm Shows |
|---|---|
| Quality Score | Overall data quality percentage computed across all active metrics |
| Status | Review state (e.g., READY FOR REVIEW) and criticality badge |
| Key Metrics | VOLUME (row count), SCHEMA (column count), FRESHNESS (time since last update), METRICS (total quality metrics defined) |
| Description | AI-generated or manually verified description of the asset |
| Semantic Context | Domain, Application, Product, and Tag classifications |
| Owners | Business owner, Technical owner, and Steward contacts |
| Lineage Summary | One-hop upstream sources and downstream consumers |
| Context Panel | AI-generated narrative, context completeness score (0–100%), and freshness timestamps for description, terms, and owner verification |
The Attribute tab lists every column Prizm has cataloged — data type, quality score, alert/issue counts, and the number of quality metrics defined.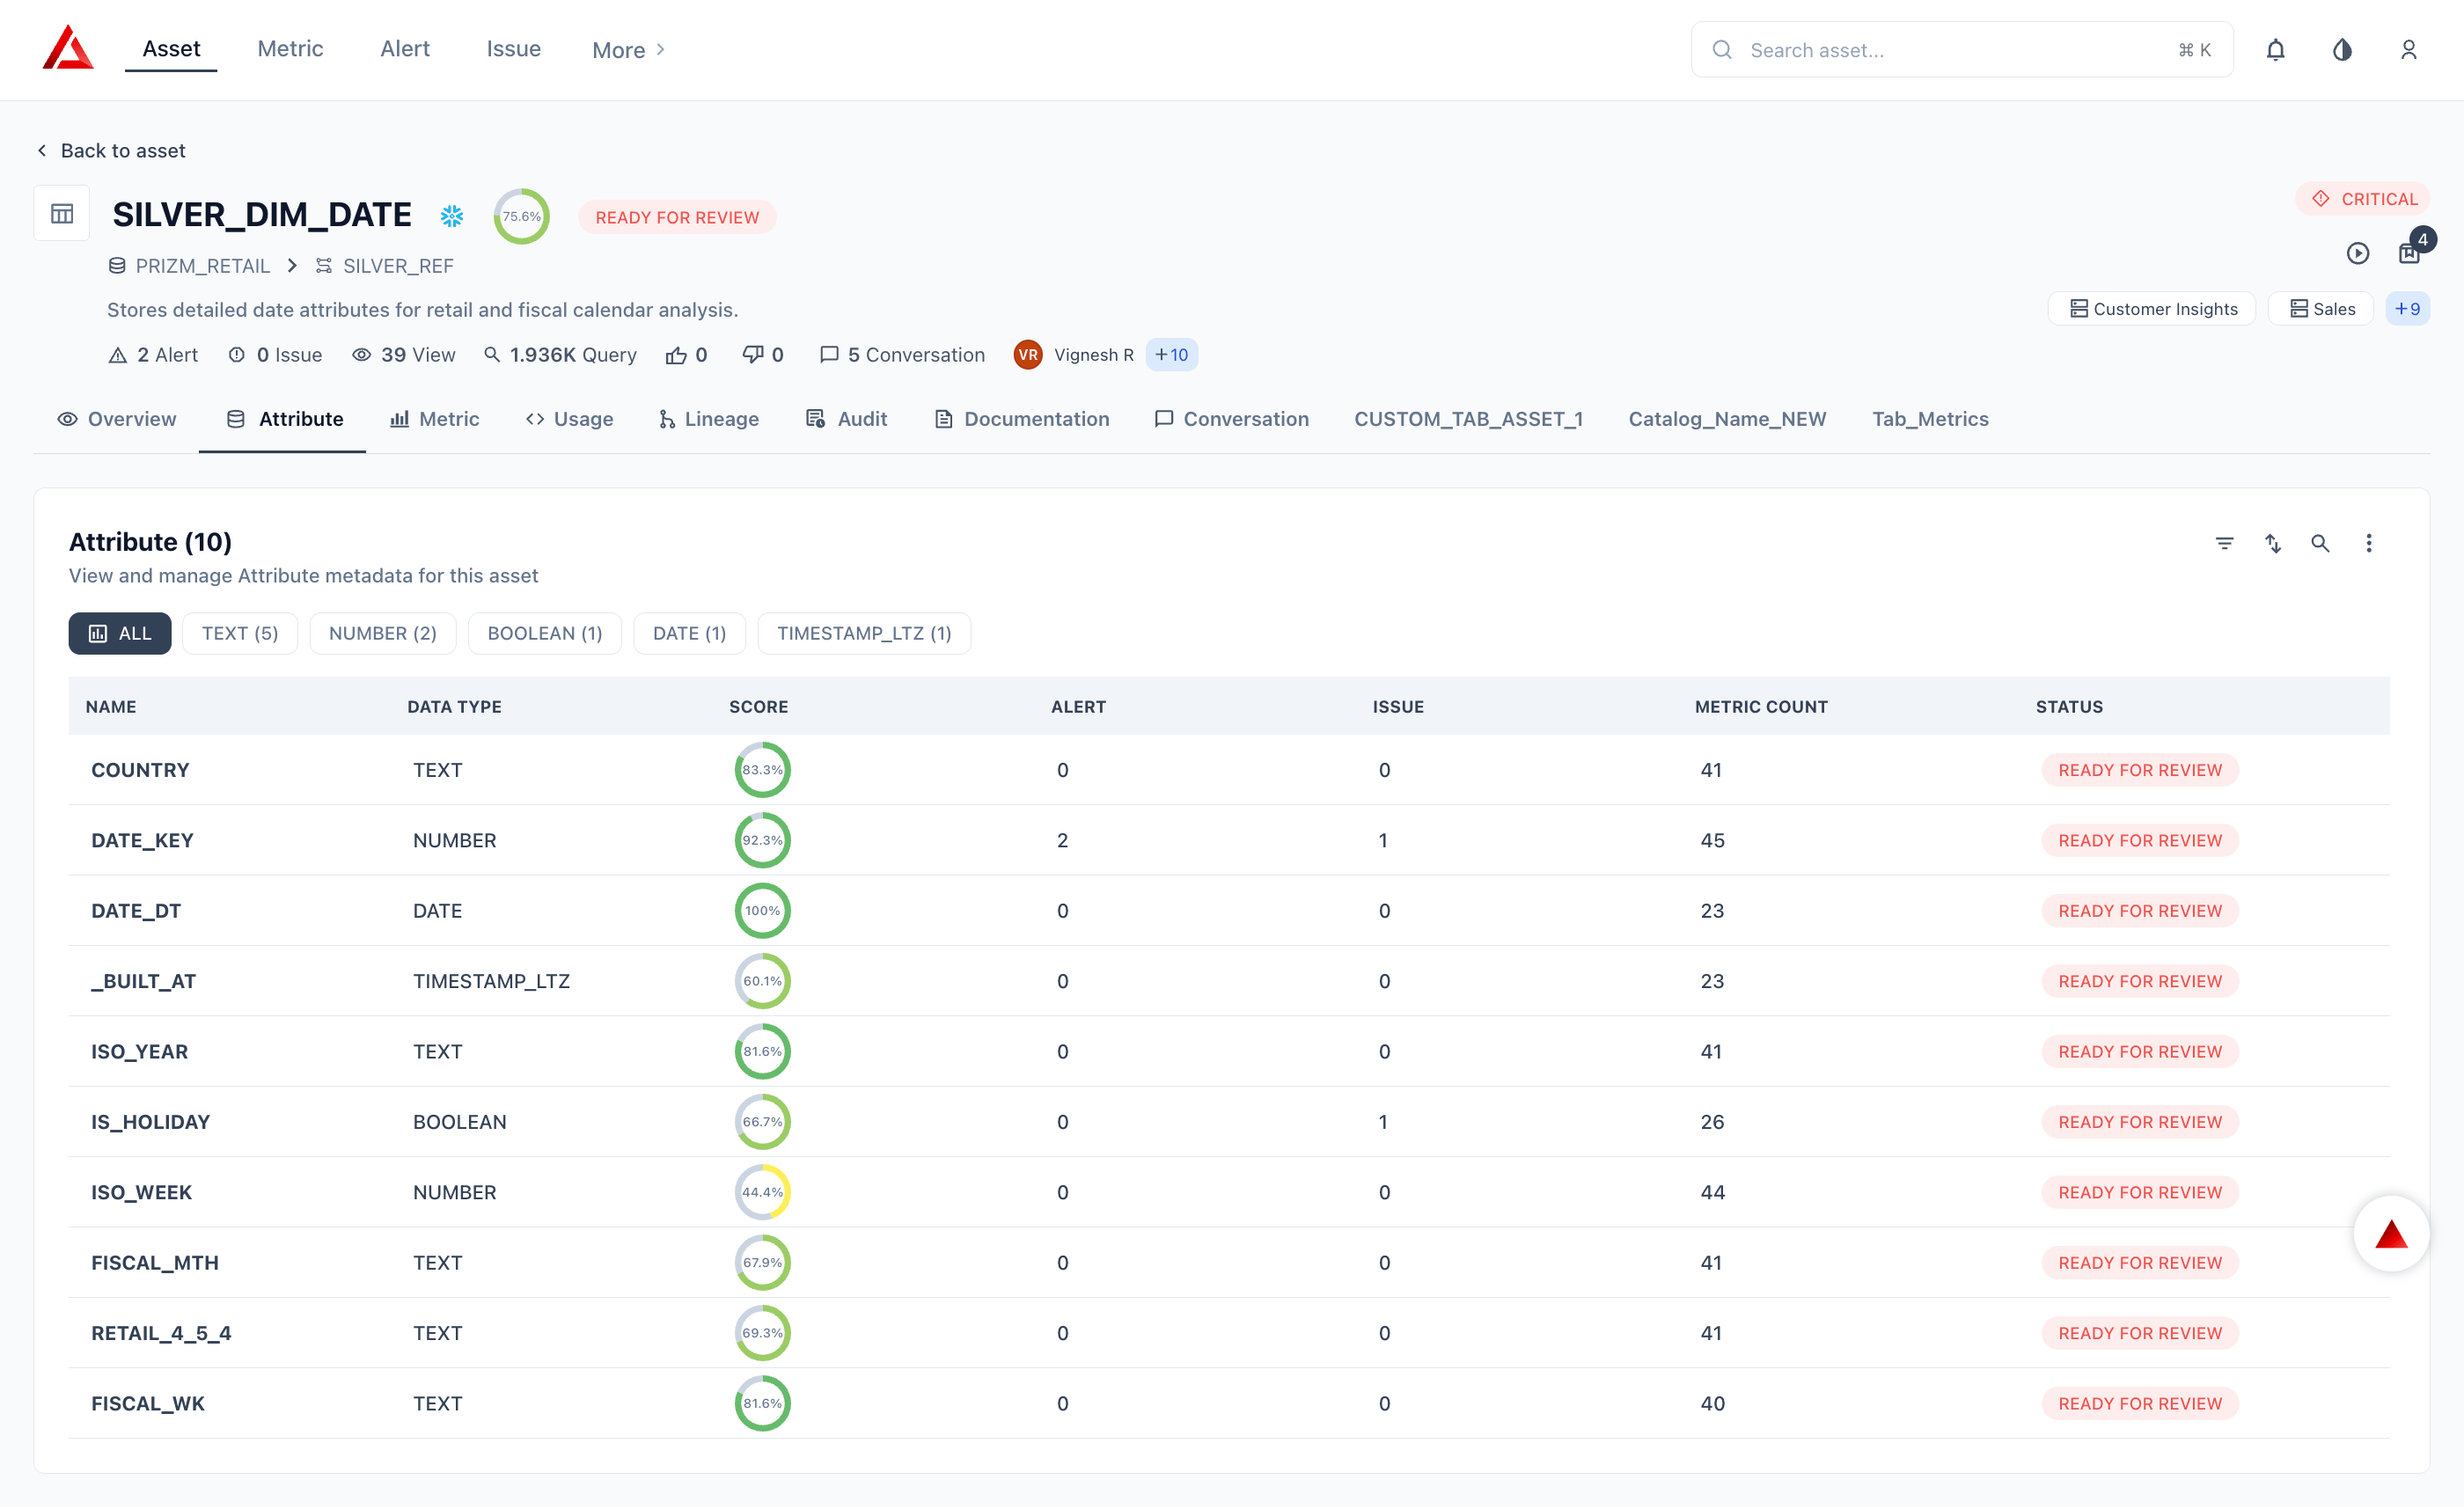
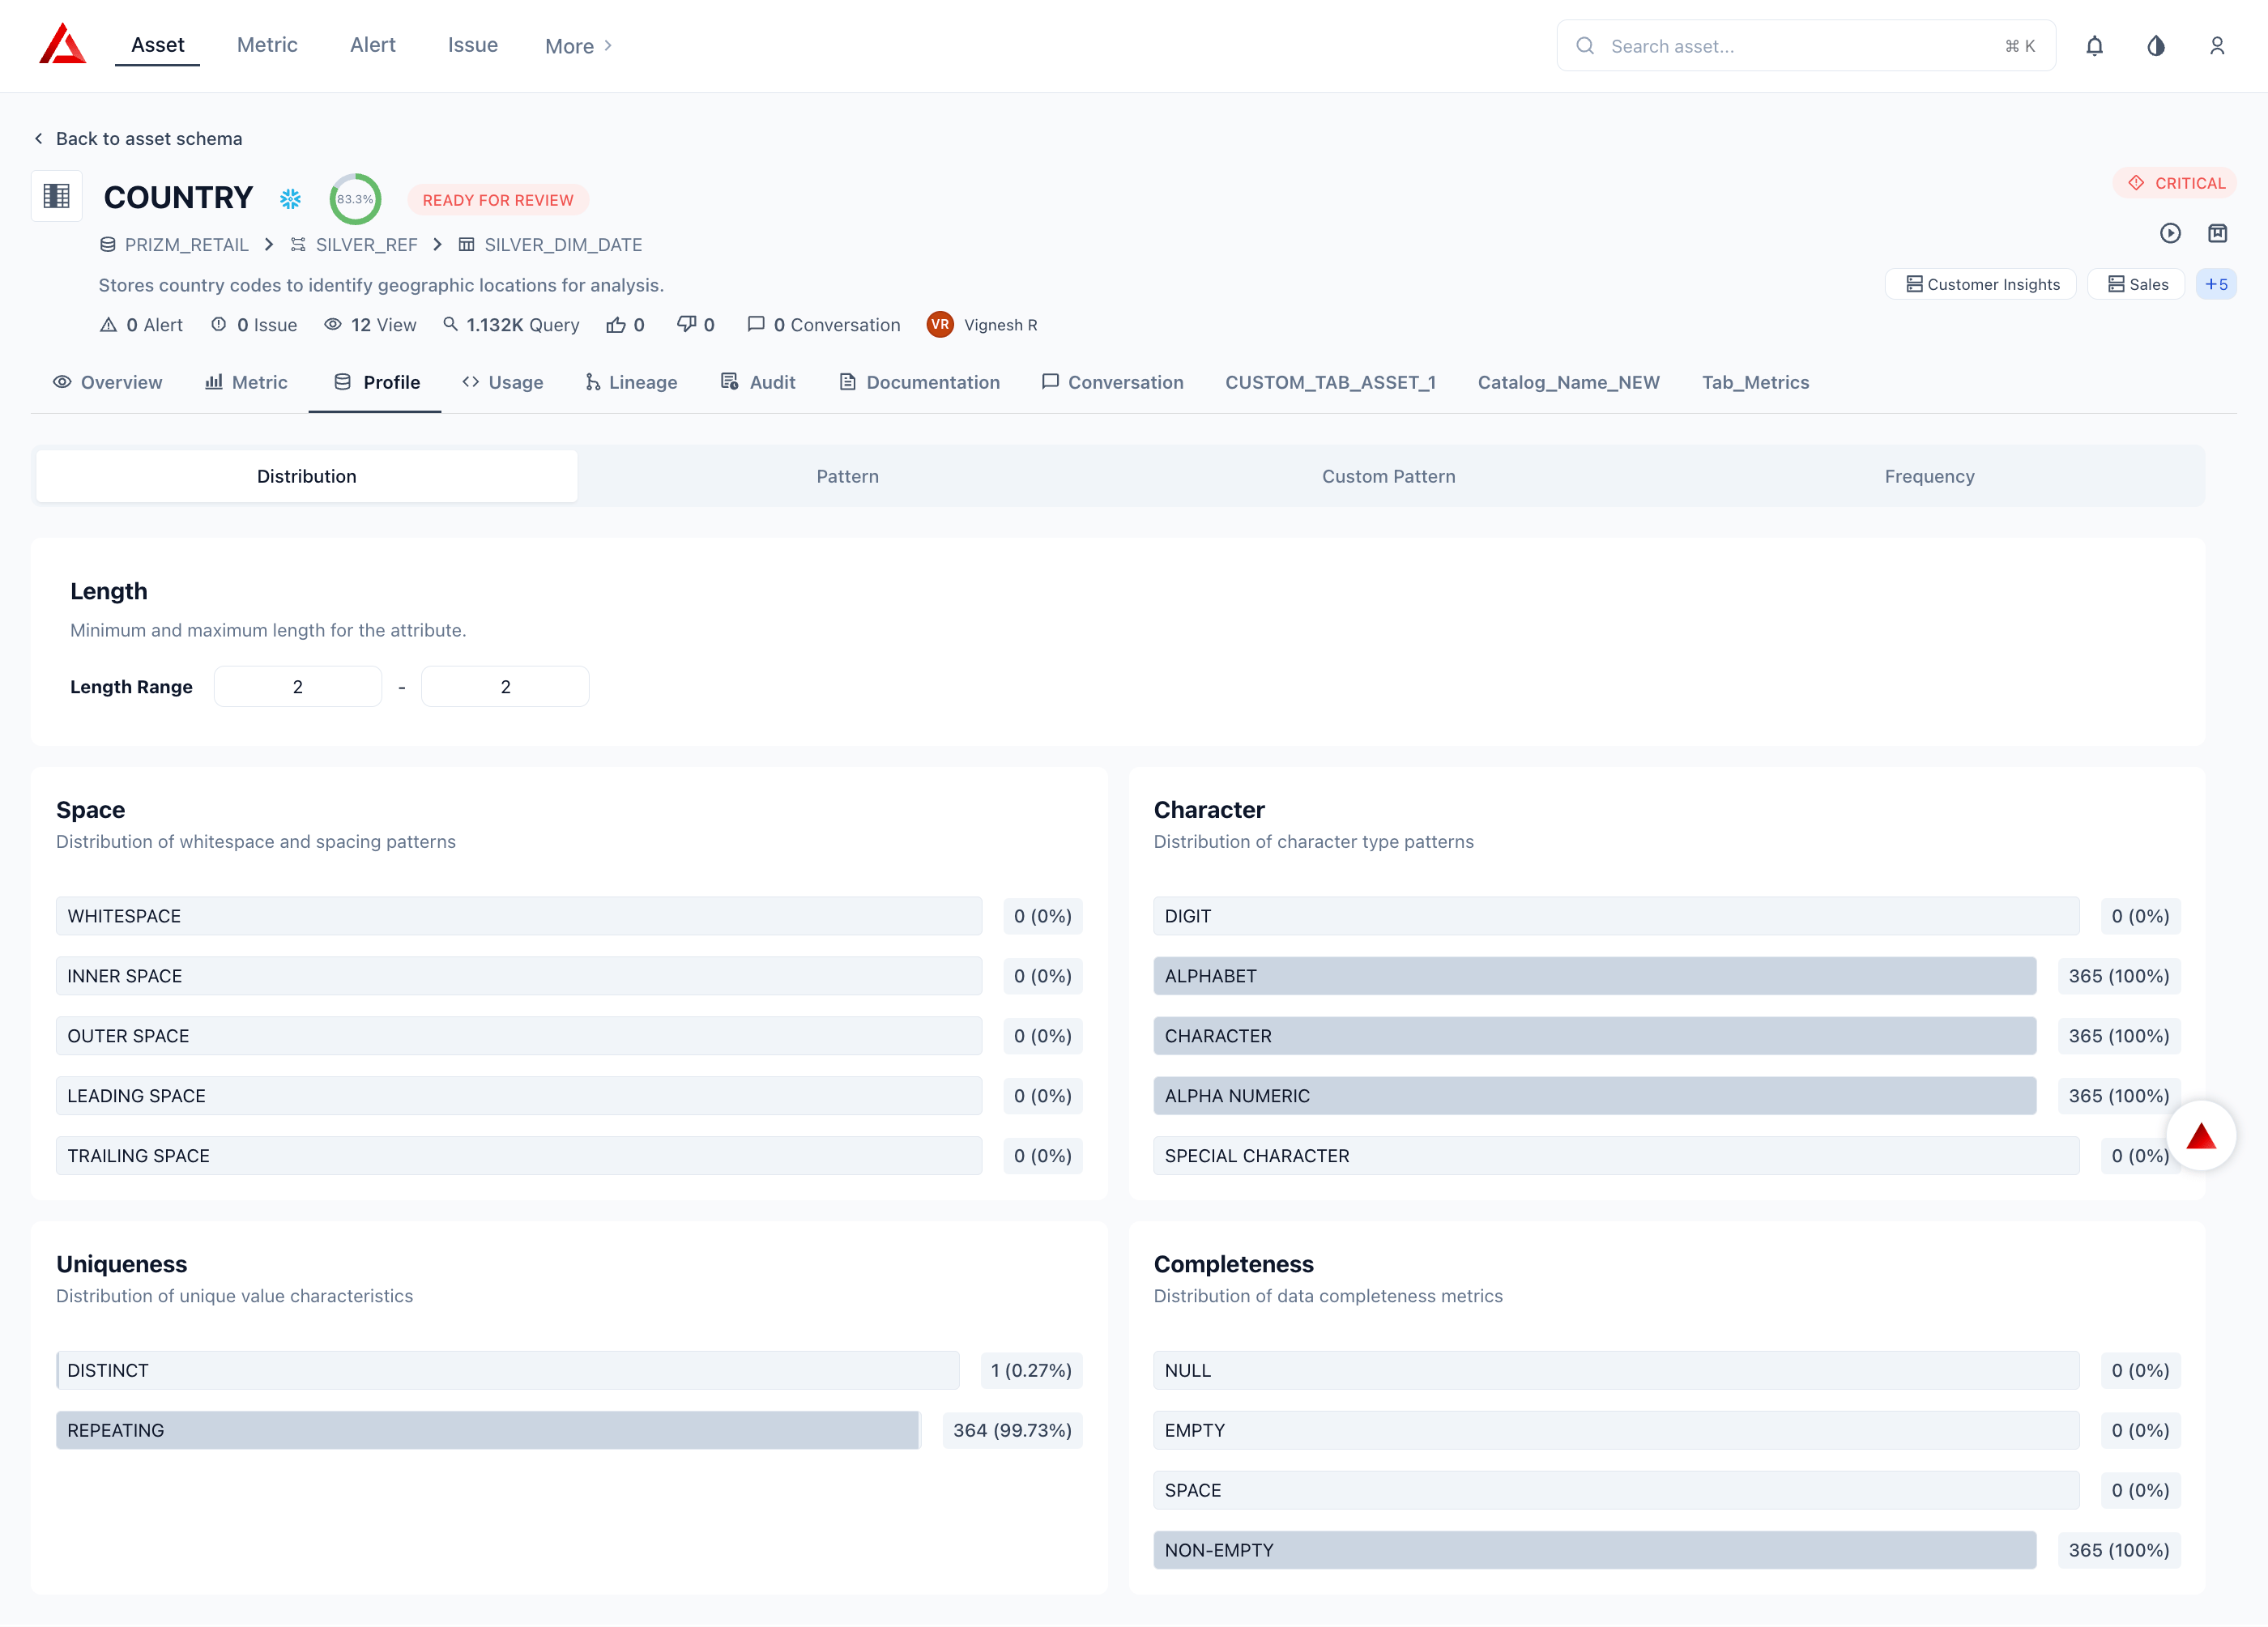
For the full breakdown of profiling views, metric types, and how to interpret profile results, see the Data Profiling section.
| Profile Section | What Prizm Shows |
|---|---|
| Completeness | Count and % of NULL, EMPTY, SPACE, and NON-EMPTY values |
| Uniqueness | Count and % of DISTINCT vs REPEATING values |
| Character | Distribution across DIGIT, ALPHABET, ALPHA NUMERIC, SPECIAL CHARACTER |
| Length | Minimum and maximum character length |
| Pattern | Top regex patterns detected across values |
| Frequency | Most and least frequent individual values |
The Metric tab lists all quality metrics defined on the asset, grouped by context. Each row shows the metric name, column, domain, current score, alert count, issue count, and action controls.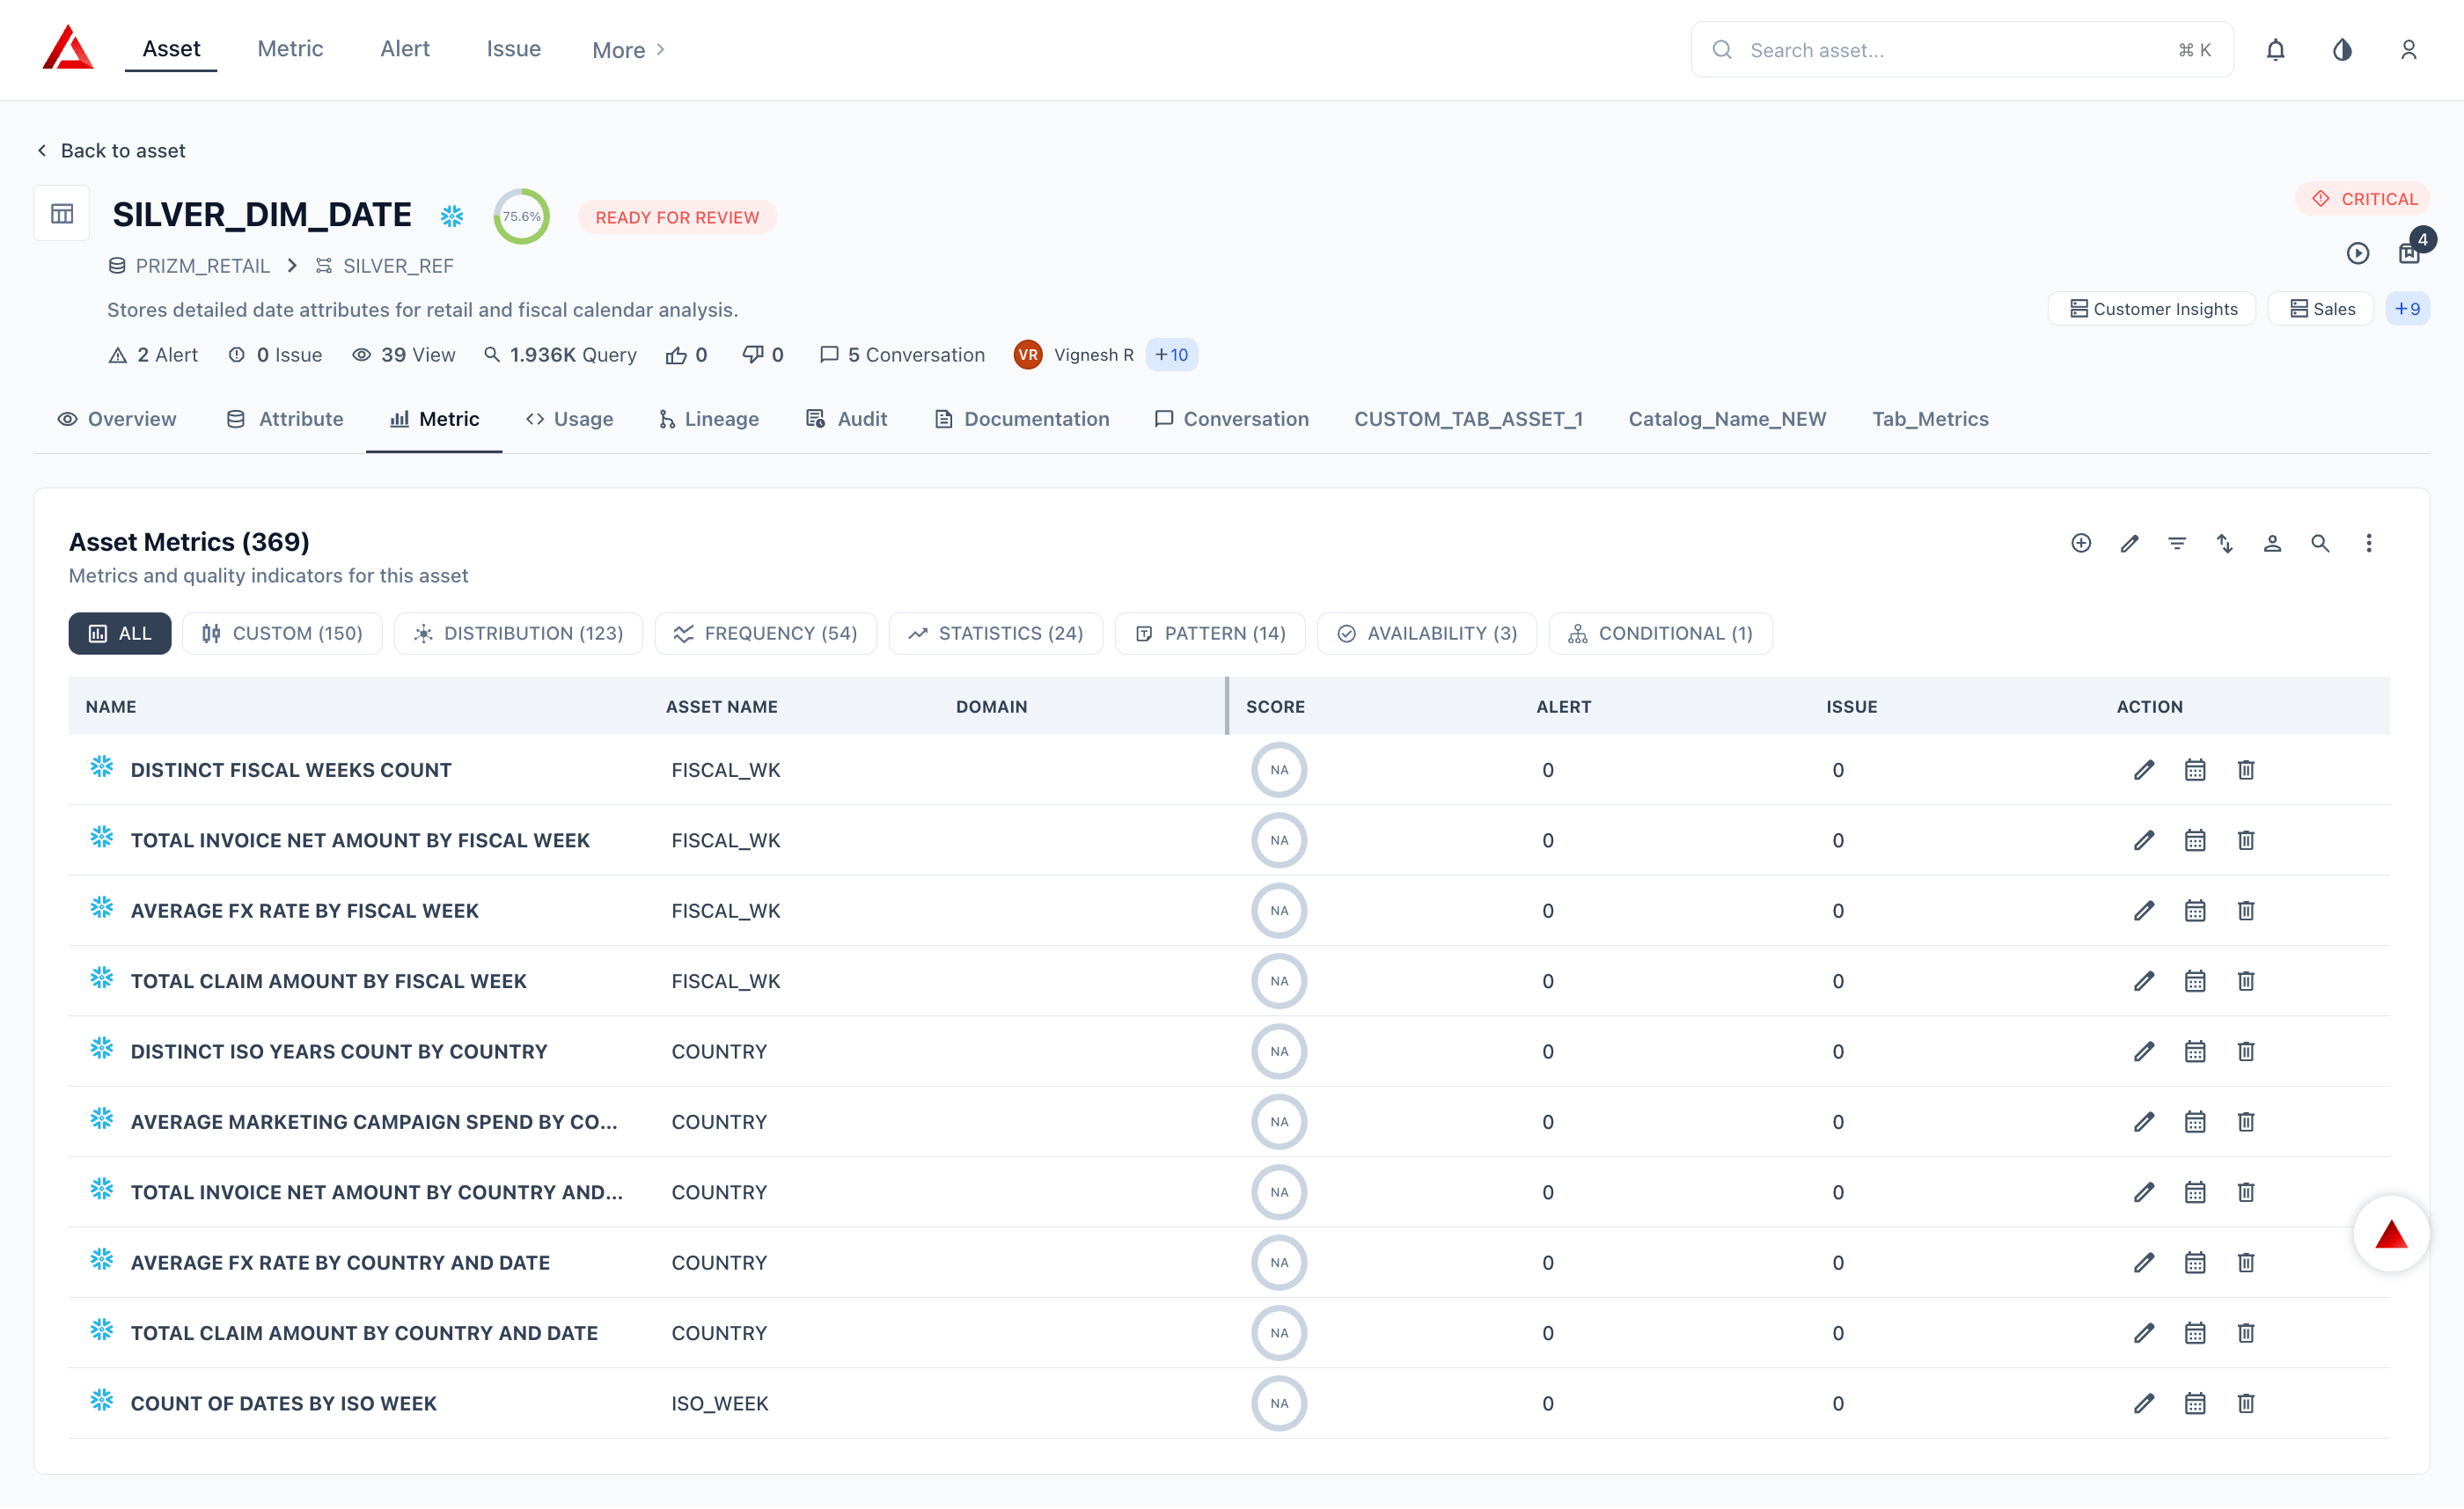
- Operational
- Structural
- Business
- Performance
- Reconciliation
- Semantics
Asset-level health signals. Monitor: Yes — Score: No
| Metric | Subcategory | Description |
|---|---|---|
| Row | Volume | Total number of rows at the time of last scan |
| Volume | Volume | Combined row count and data size signal |
| Data size | Volume | Physical size of the asset in bytes |
| Freshness | Freshness | Time elapsed since the asset was last updated |
| Last updated | Freshness | Timestamp of the most recent data load or write |
| Column | Schema | Current number of columns |
| Schema | Schema | Full column snapshot — names, types, and order |
| Schema name | Schema | Name of the schema the asset belongs to |
| Duplicates | Duplicate | Count of duplicate rows based on a defined key or all columns |
Auto-generated column-level metrics. Score: YesDistribution
Frequency
Pattern
Statistics
| Metric | Subcategory |
|---|---|
| Null count | Completeness |
| Empty | Completeness |
| Non-empty | Completeness |
| Space | Completeness |
| Zero value | Numeric |
| Distinct | Uniqueness |
| Repeating | Uniqueness |
| Leading space | Space |
| Trailing space | Space |
| Inner space | Space |
| Outer space | Space |
| Whitespace | Space |
| Character | Character |
| Alpha numeric | Character |
| Digit | Character |
| Special character | Character |
| Alphabet | Character |
| Positive | Numeric |
| Negative | Numeric |
| Metric | Subcategory |
|---|---|
| Enum | Value |
| Min value | Value |
| Max value | Value |
| Value range | Range |
| Min length | Length |
| Max length | Length |
| Length | Length |
| Length range | Range |
| Metric | Subcategory |
|---|---|
| Short pattern | Pattern |
| Long pattern | Pattern |
| Regular expressions | Pattern |
| Metric | Subcategory |
|---|---|
| Mean | Descriptive |
| Median | Descriptive |
| Mode | Descriptive |
| Standard deviation | Descriptive |
| Sum | Descriptive |
| Q1 | Quantile |
| Q3 | Quantile |
| Range | Shape |
| Skewness | Shape |
| Kurtosis | Shape |
| Variance | Shape |
| Margin of error | Shape |
User-defined metrics. Custom, Conditional, Standalone: Score Yes — Behavioral: Score No
| Metric Type | Description |
|---|---|
| Custom | User-defined rules, filters, or expressions on a specific asset |
| Conditional | Different logic or thresholds based on a condition |
| Query | SQL query returning a scalar — enables multi-table logic |
| Standalone | Not bound to a specific asset — used for org-wide KPIs |
| Behavioral | Tracks patterns over time — detects drift, not point-in-time violations |
Platform-level signals. Monitor: Yes — Score: No
| Metric | Level |
|---|---|
| Total queries per day | Warehouse, Database |
| Query success rate | Warehouse, Database |
| Execution time | Warehouse, Database |
| Job duration | Warehouse, Database |
| Test execution time | Warehouse, Database |
| Avg blocked | Warehouse, Database |
| Avg queue load | Warehouse, Database |
| Avg running | Warehouse, Database |
| Database storage | Database |
| Total credits per day | Warehouse, Database |
| Credits used | Warehouse, Database |
Cross-source comparison metrics.
| Metric Type | Description |
|---|---|
| Comparison | Compares values, row counts, or aggregates across two registered assets |
| Lookup | Validates column values against a reference table or allowed set |
Domain and grouping level metrics.
| Grouping | Description |
|---|---|
| Domain | DQ score rolled up across all assets assigned to a domain |
| Product | Aggregate quality and freshness across a defined data product |
| Application | % of assets in an application meeting quality and freshness SLOs |
| Tag | PII tag coverage across assets with sensitive columns |
| Connection | Aggregate quality score across all assets from a given Snowflake connection |
The Usage tab surfaces per-asset query intelligence derived from the Performance job.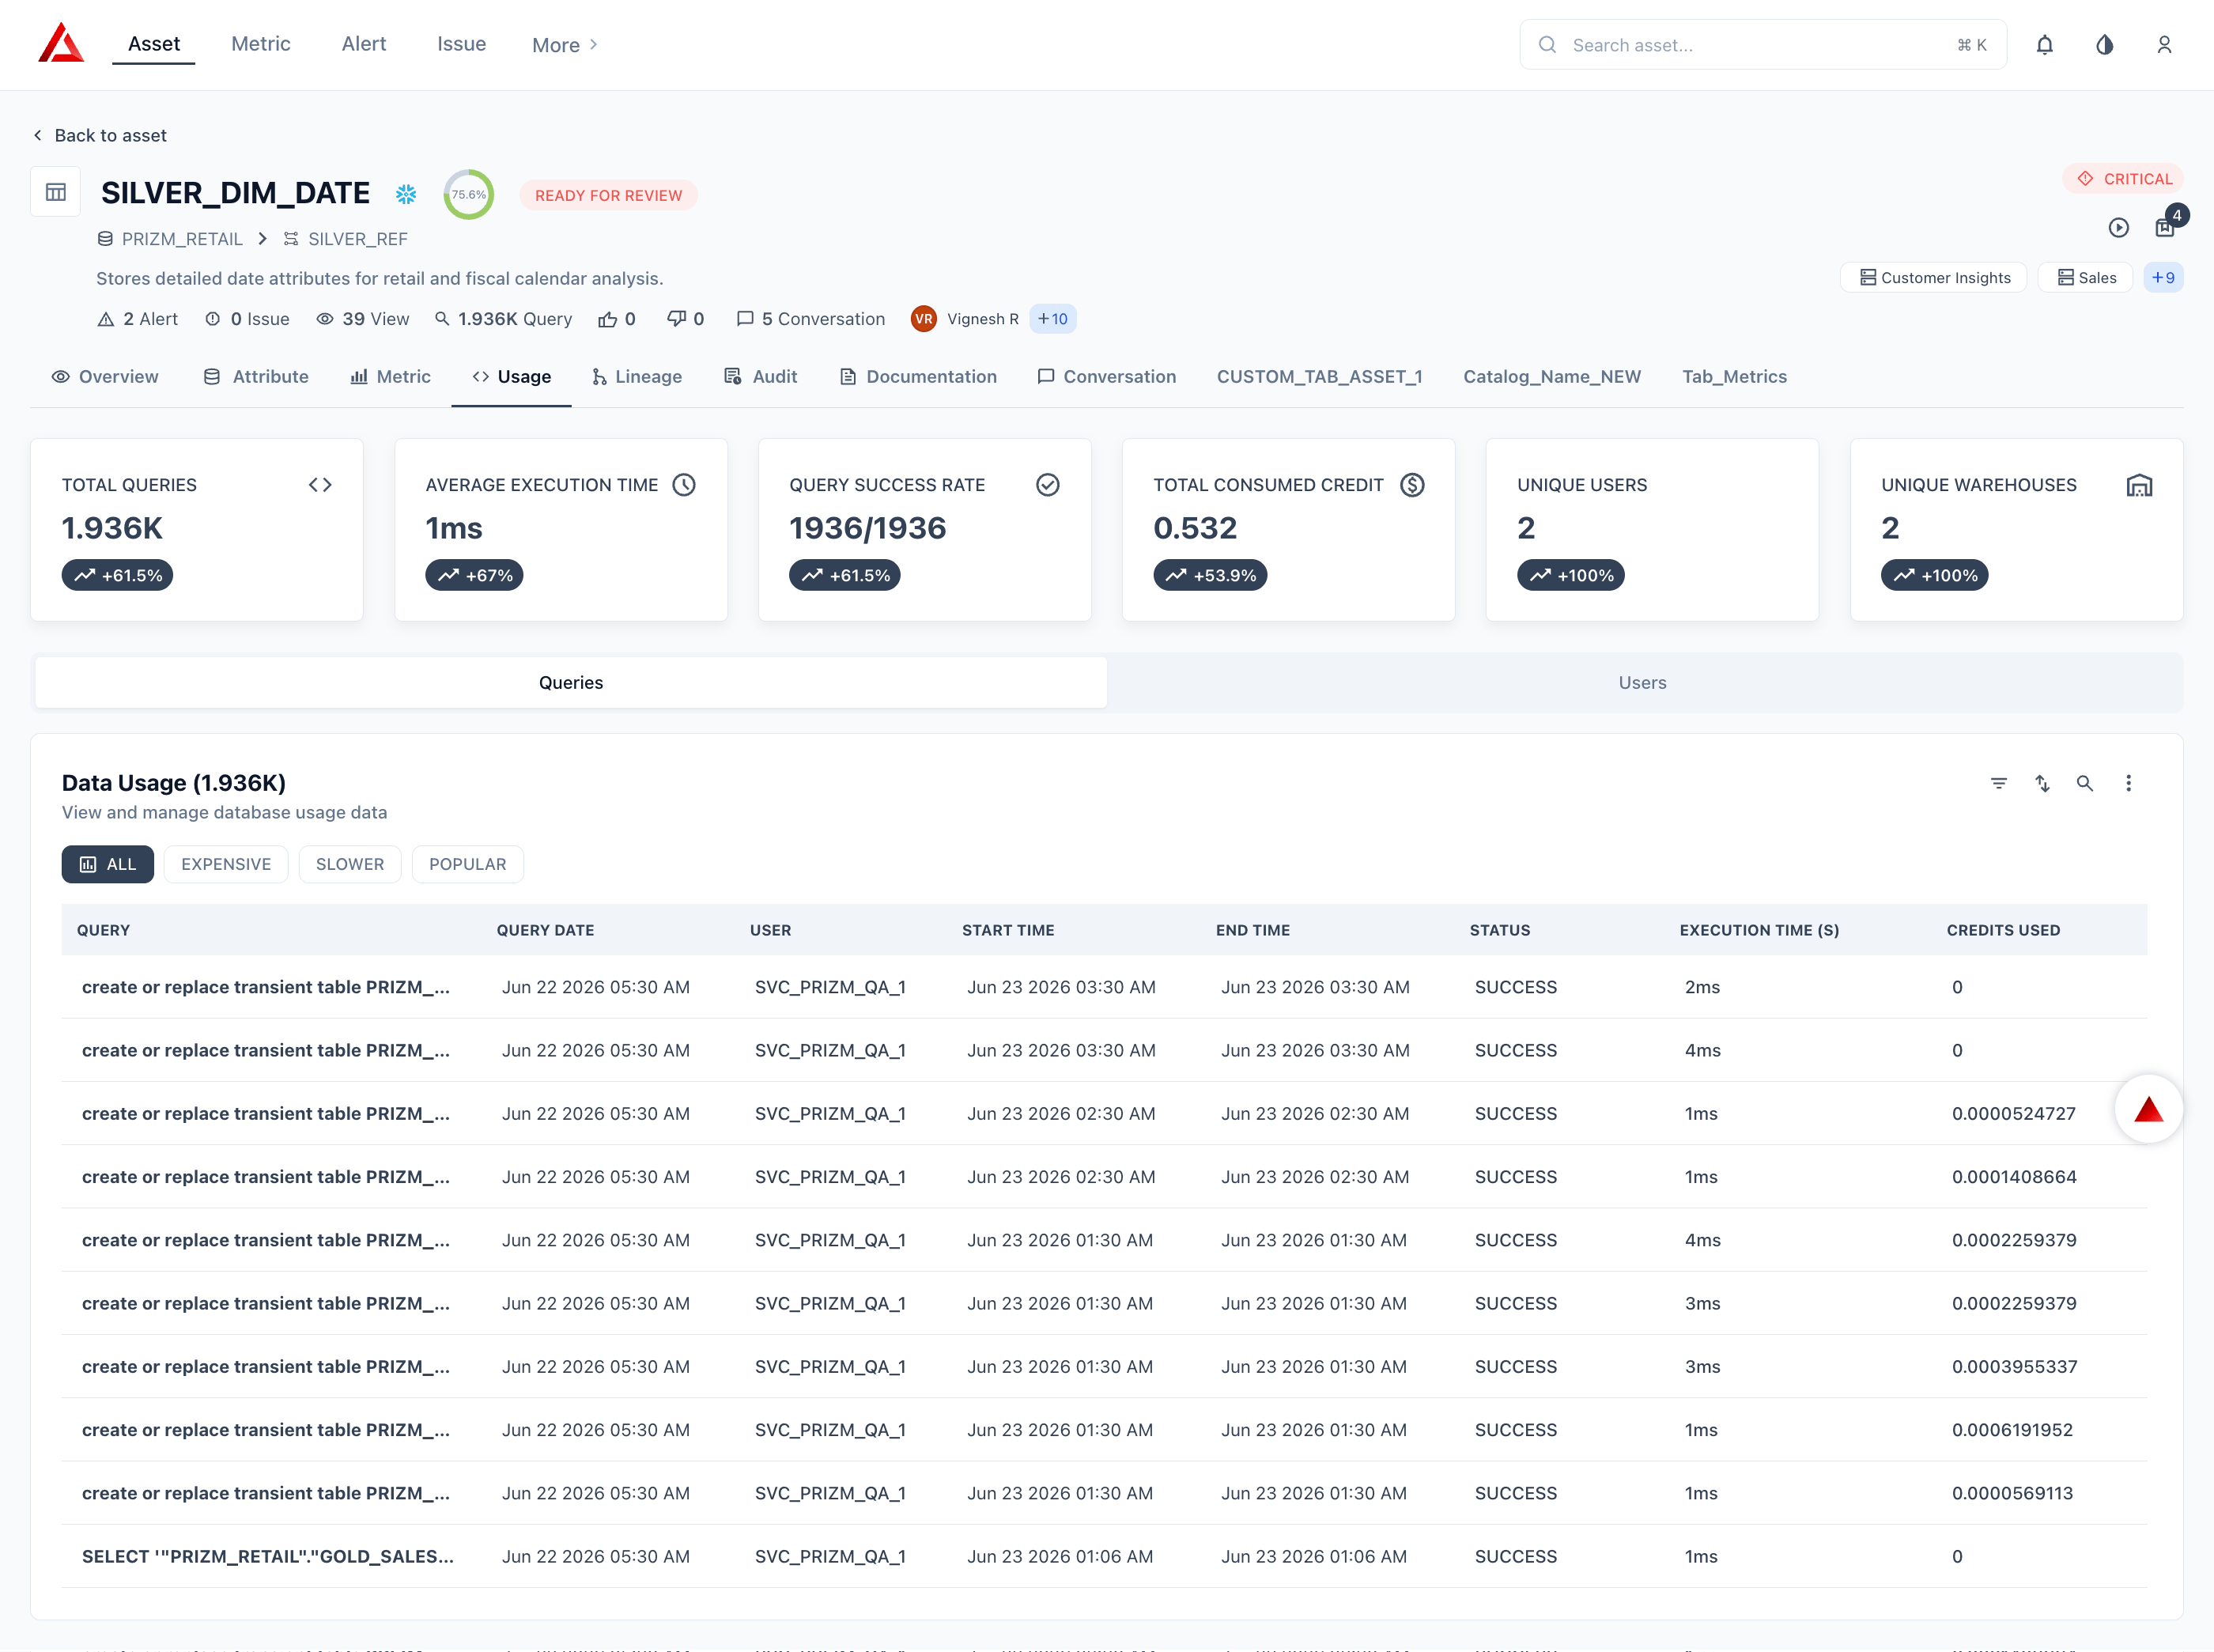
Queries can be filtered by EXPENSIVE, SLOWER, and POPULAR.
| Metric | Description |
|---|---|
| Total Queries | Total number of queries that touched this asset |
| Average Execution Time | Mean query execution time in milliseconds |
| Query Success Rate | Ratio of successful queries to total queries |
| Total Consumed Credit | Snowflake credits consumed by queries against this asset |
| Unique Users | Number of distinct users who queried this asset |
| Unique Warehouses | Number of distinct warehouses used to query this asset |
The Lineage tab renders an interactive directed graph of all upstream sources and downstream consumers. Click any node to navigate to that asset’s detail page.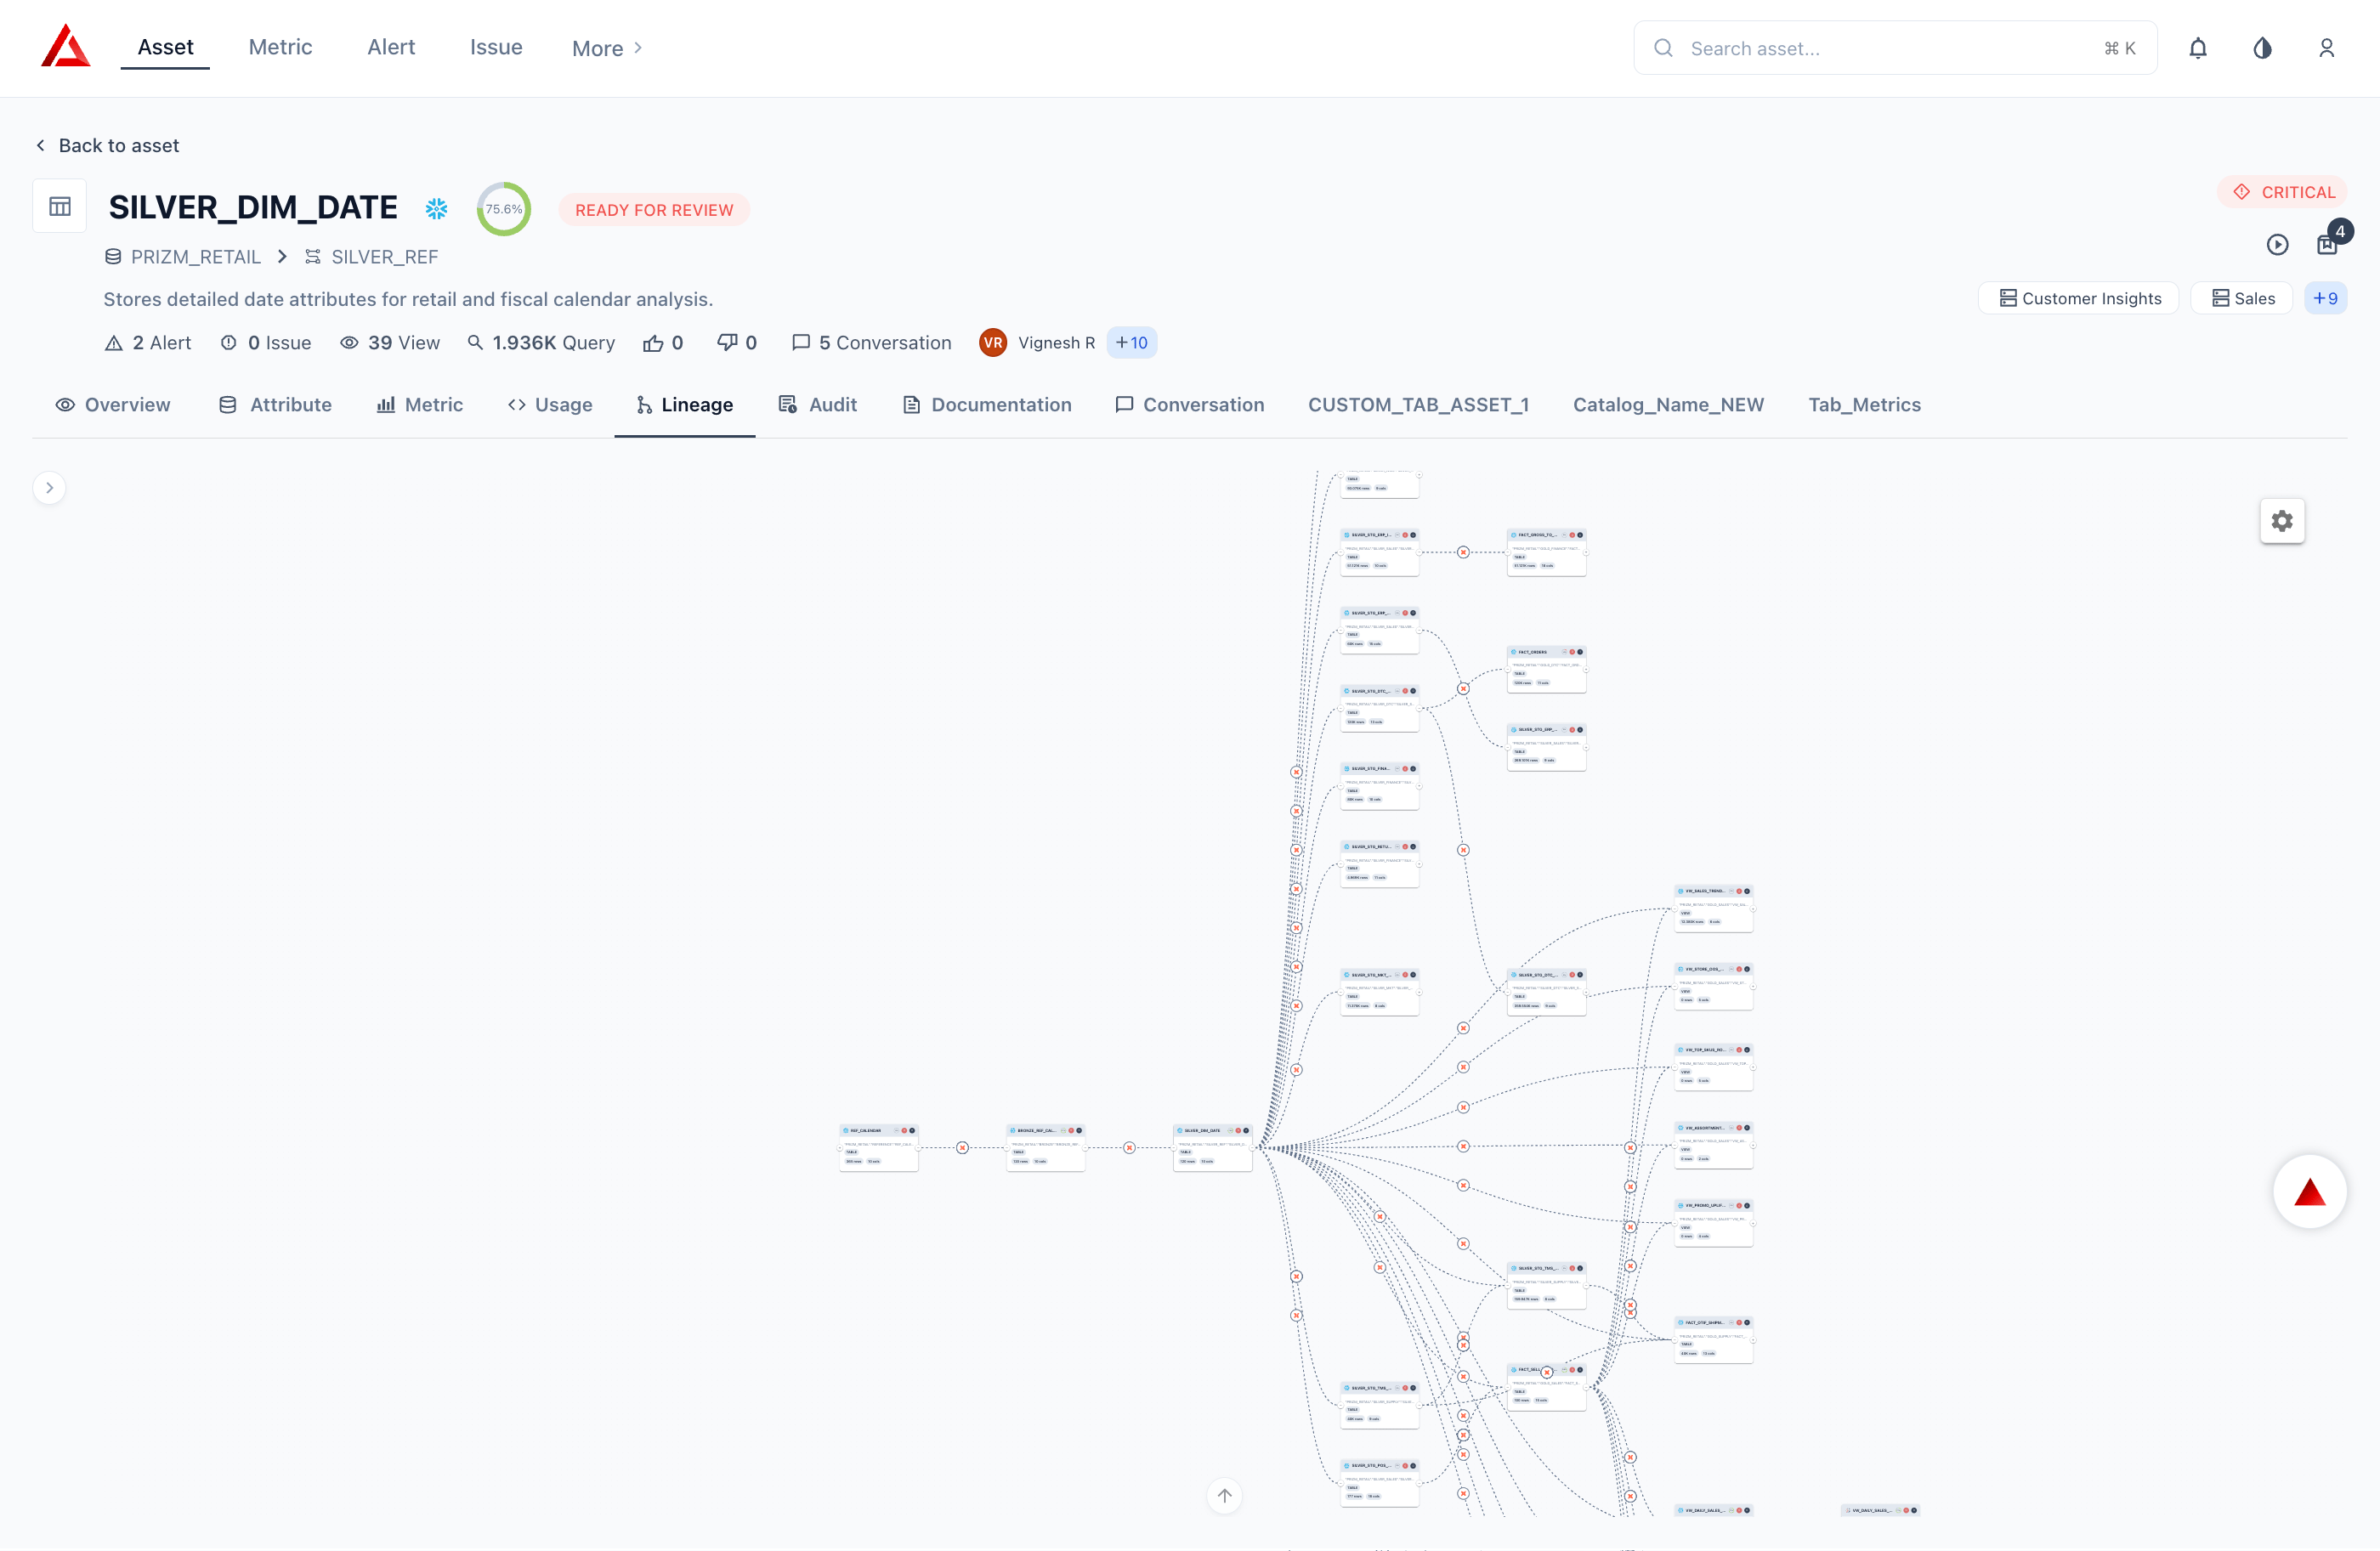
Next Steps
Setup
Review prerequisites and configure the connector.
FAQ
Common questions about what Prizm collects and why.