
Observability is a separate signal from Quality: Quality scores correctness (DQ measures), Observability tracks reliability (did data arrive on time, in the expected volume, with the expected schema). An asset can be observability-healthy and still fail quality checks, or vice versa.
Layout
The tab is laid out top to bottom as: the three uptime tiles, the AI summary, the four count tiles, the Alert and Issue heatmaps side by side, the Recent schema changes table, and the Unhealthy assets table. Every tile and widget respects the filter bar and the date range.KPI cards
Uptime tiles

The three uptime tiles. Each shows the uptime for the date range and the change against the prior window of the same length.
Under each percentage a badge compares it with the same uptime measured over the window immediately before the date range, for example
-2.12% vs 99.89% prior 90d. The label follows your range: with Last 90 days it reads prior 90d, and with a 14-day range it reads prior 14d. The badge shows the change in percentage points and the prior window’s own value.
AI Summary

AI summary for the Observability (Data) tab.
Count tiles

The four count tiles, each with a comparison against the prior window.
Each count tile carries a badge such as
+217 vs 1 prior 90d: the change from the prior window of the same length, followed by the prior window’s own count. A downward arrow means fewer than before. For these counts a lower number is better, so a rise in anomalies, schema changes or freshness alerts is the signal to investigate.
Widgets
Alert heatmap
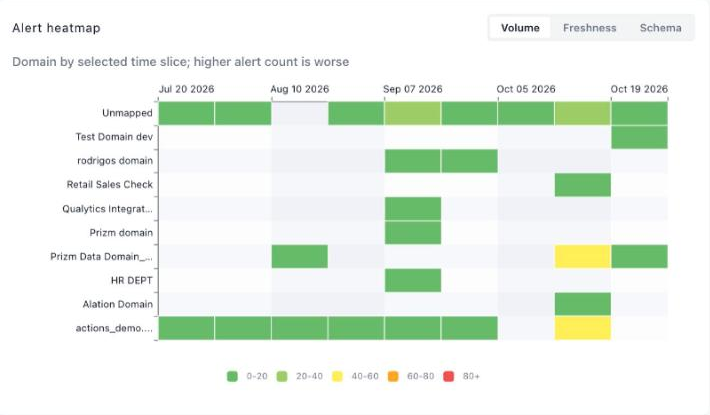
Alert heatmap, Volume tab. Rows are domains and columns are Slice By buckets.
Domain by selected time slice; higher alert count is worse. The legend runs 0-20 green → 80+ red, because for alerts higher is worse — this is the inverse of the Quality Dashboard’s score heatmaps, where green means a high (good) score. Assets that are not assigned to a domain are grouped under Unmapped, and a pale cell means no alerts in that bucket. Use it to find the domains and weeks with the noisiest or least stable data.
Issue heatmap
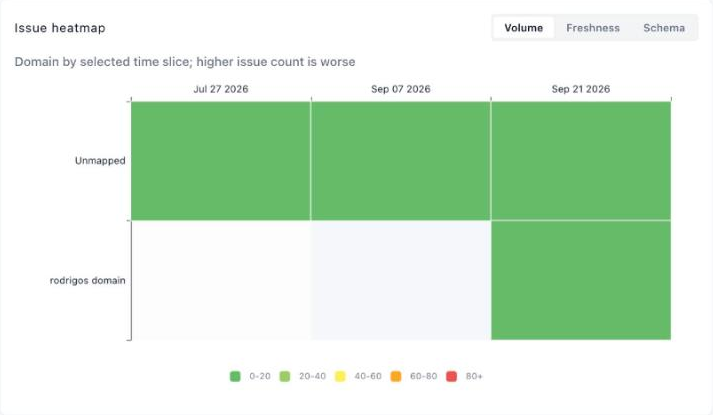
Issue heatmap, Volume tab. Same layout as the Alert heatmap, counting issues.
Recent schema changes
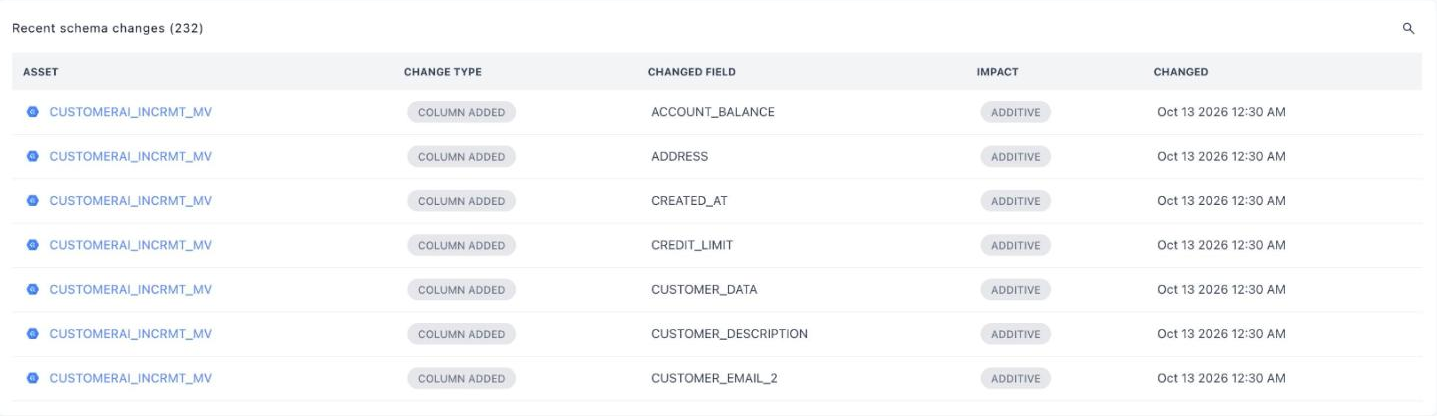
Recent schema changes. The number in the title is the count of change events in scope.
Unhealthy assets
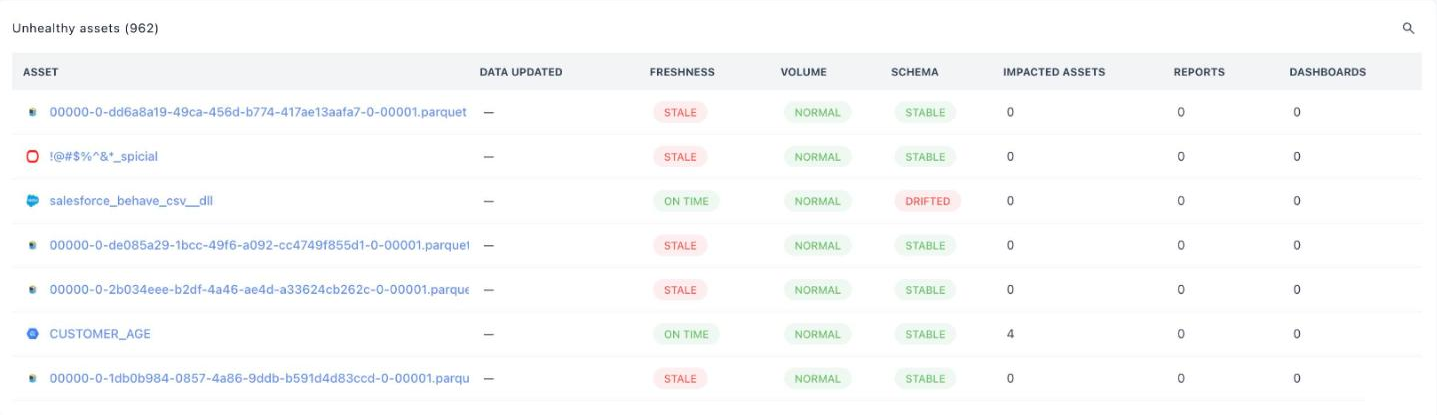
Unhealthy assets. The number in the title is the count of assets with at least one reliability problem.
— when the asset has no recorded update), Freshness (for example Stale or On time), Volume (for example Normal), Schema (for example Stable or Drifted), Impacted Assets, Reports, Dashboards (downstream BI impact counts via lineage). Use the three impact columns to prioritise: an unhealthy asset with downstream reports and dashboards matters more than one with none.
Filters

Filter bar on the Observability (Data) dashboard
prior 90d or prior 14d. With Match Slice By the tiles narrow to the latest Slice By bucket and compare it with the bucket before it, and the label changes to match (for example prior week). See Previous Period and the KPI badges.
Slice By: time-bucket granularity for the heatmaps
Slice By offers the same six options as elsewhere (Day, Week, Month, Quarter, Half-year, Year; defaults to Week). On this dashboard it rebuckets the column headers of the Alert heatmap and Issue heatmap — it does not change any KPI tile. Worked example, no other filters applied:
Only the heatmaps’ column buckets changed — every KPI tile stayed identical, the same pattern documented for the Quality Dashboard’s trend chart and heatmaps.
With filter vs. without filter: a worked example
Example captured during validation, Last 90 days, no Slice By change:
Narrowing to a single asset type reduces every count tile (fewer matching assets/events) and, in this snapshot, also reduced the uptime percentages slightly — tables in this environment had a somewhat worse reliability record than the full asset population over the period. The same mechanism applies to every other filter field and to combinations of them.
The exact figures above are an illustrative example and will not match your environment. The relationship they demonstrate — filtering narrows the population, Slice By only rebuckets time — is what to rely on, not the specific numbers.
Related pages
Catalog Dashboard
The Catalog tab of Analytics — asset discovery, classification coverage, and governance health
Quality Dashboard
DQ score, alerts, and issues — the correctness counterpart to this reliability dashboard